

Over the past year, I’ve been deep in the weeds of AI search, studying and breaking down concepts such as vector embeddings, RAG (Retrieval-Augmented Generation), cosine similarity, agentic search and the like.
Query fan-out falls in this category. It’s one of the main ideas I keep returning to, ever since Google introduced it at I/O 2025.
I’ve done quite a bit of work on this, from writing think pieces on Moz & iPullRank to carrying out a number of smaller experiments. For example, in one of my recent LinkedIn posts, I explored how often Gemini expanded a question into additional searches, and eventually built a recursive network of 2,400+ queries to see how far one question could drift as the model kept expanding it.
In another case, I wrote an article about the topic on Backlinko and presented some of that work at the Sip & Search event in London.
Rather than just clinging onto fan-out as a new, shiny AI-search term, my aim instead was to deeply understand what these hidden queries mean for brands trying to appear in answers that are contextual, probabilistic and increasingly difficult to reverse-engineer.
So yeah, I’ve been down this rabbit hole for a while. That’s why, when GPT-5.6 arrived, I saw it as an opportunity to push my work further with a larger dataset (compared to others I worked with previously).
For this study, I ran 1,500 prompts (across 10 verticals) through the OpenAI Responses API using GPT-5.6 Terra, medium reasoning and web search enabled. The experiment produced 4,719 fan-outs, 4,533 citation appearances across 955 domains and 18.34 million input and output tokens.
Why I Used Terra Rather Than Sol or Luna
OpenAI recently released GPT-5.6 as a family of three model tiers: Sol, Terra and Luna.
Sol is positioned as the flagship model for complex professional work, Terra as the balance between intelligence and cost, and Luna as the faster, lower-cost option for high-volume workloads.
I chose Terra because it was the most realistic model for this particular experiment. I wasn’t trying to measure the most powerful model; rather, I wanted to run a large, repeatable study using the everyday, balanced work model at a cheaper cost.
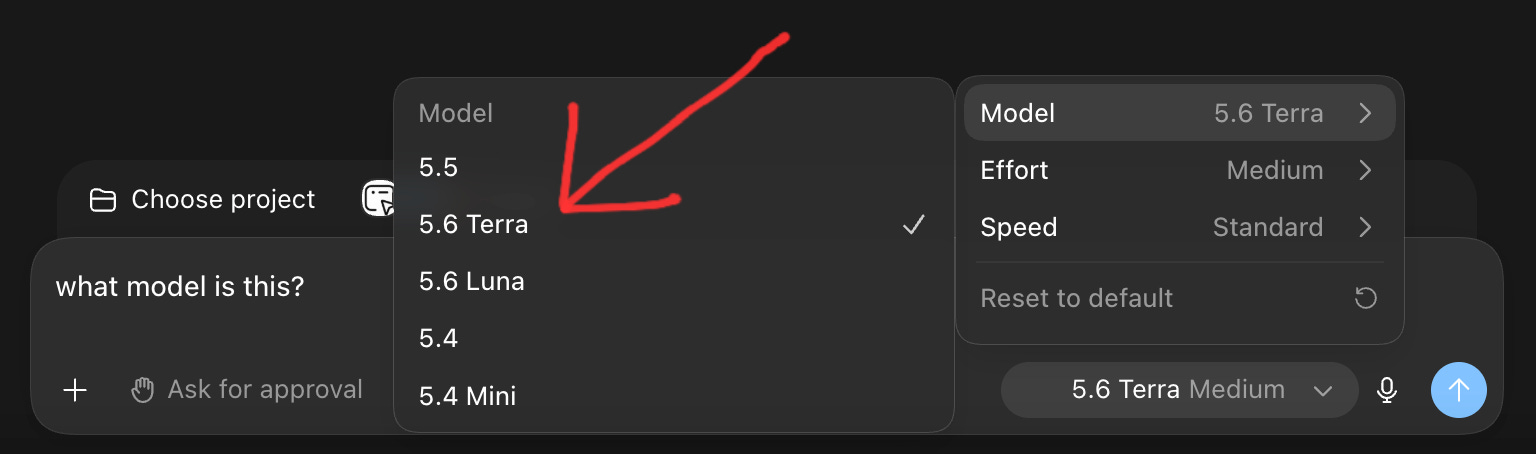
Besides, OpenAI says Terra performs just above Fable 5, and surpasses GPT‑5.5’s peak performance at half the input and output token cost, so yay, I guess.
Down to the technical details: I used the API rather than the web interface because I needed each prompt sent without conversation history, and to extract the raw JSON response at scale. That doesn’t mean the web interface would behave identically; this article is specifically about the API setup I tested. I also kept the reasoning effort at medium for every prompt.
How I Built the 1,500-Prompt Test
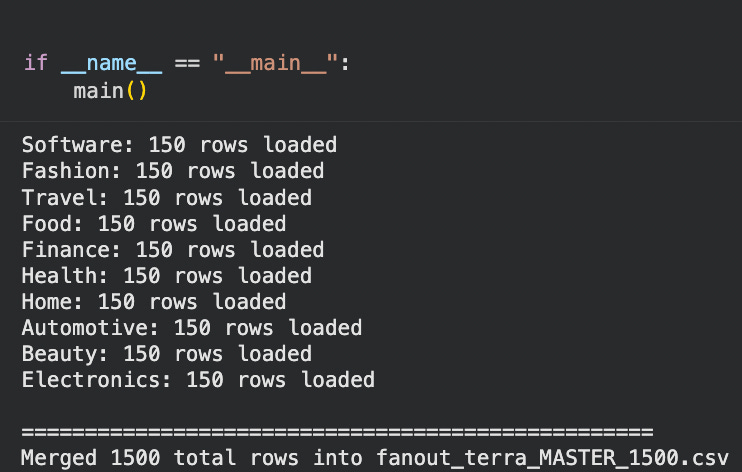
I needed enough variety to compare industries without letting one type of question dominate the experiment. The dataset covered Automotive, Beauty, Electronics, Fashion, Finance, Food, Health, Home, Software and Travel.
Each industry contained 15 subcategories, giving me 150 subcategories in total. I then applied the same 10 prompt formats to every subcategory.
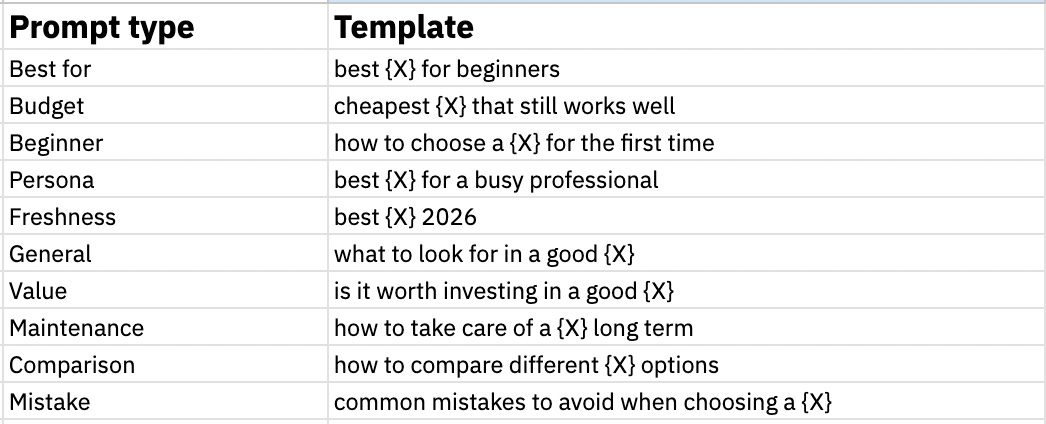
That gave every prompt type exactly 150 runs and every industry exactly 150 prompts.
Here’s an example of a subcategory (password manager) under the software vertical:
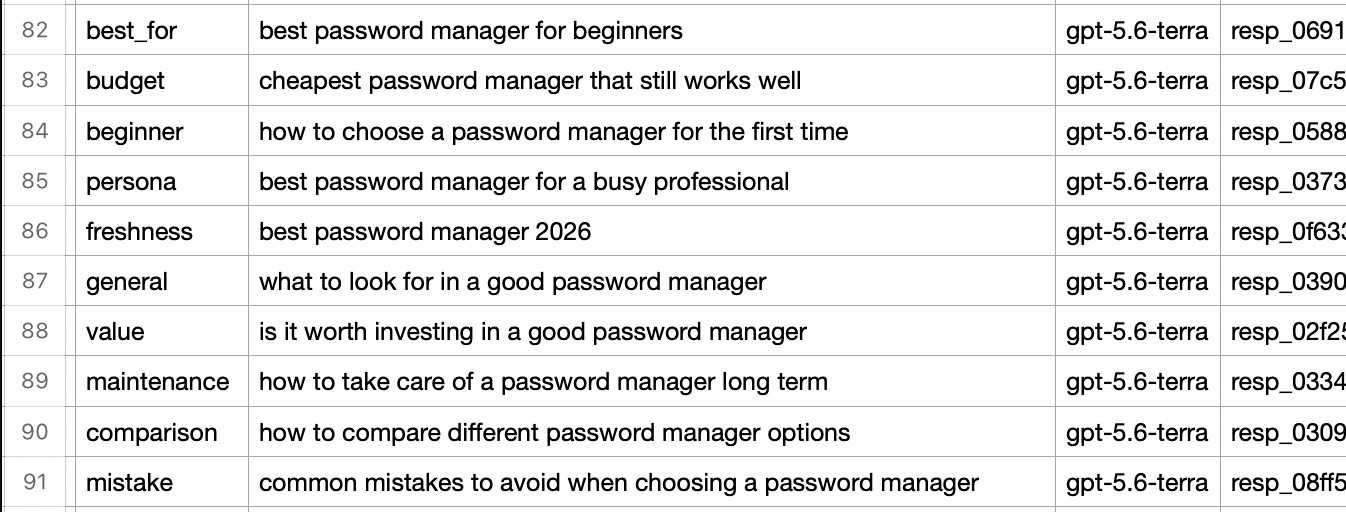
This balance matters. If all the “Freshness” prompts were about software and all the “Value” prompts were about clothing, it would be hard to know whether a difference came from the wording or the subject. Here, every framing was tested across the same broad set of industries.
For each run, I collected far more than the final answer. I saved whether search was triggered, every generated query, the number of search-call objects, pages opened, cited URLs and domains, input and output tokens, reasoning tokens, answer length and the full raw JSON response.
Disclaimer: This is a controlled practitioner experiment, not a representative sample of every ChatGPT conversation. The prompts lean towards recommendations, prices, products, comparisons and consumer decisions. Every prompt was also run once, so the study does not measure repeatability between identical runs. The safest way to read the results is as a detailed snapshot of how this model configuration behaved when the same prompt structures were applied consistently across 10 industries.
That said, let’s dig right into the findings!
Nearly 3 in 4 Prompts Turned to Web Search
This was one of the less surprising findings, but still quite useful. Of the 1,500 prompts, 1,100 (73.3%) produced at least one recorded web search. The other 400 were answered without one.
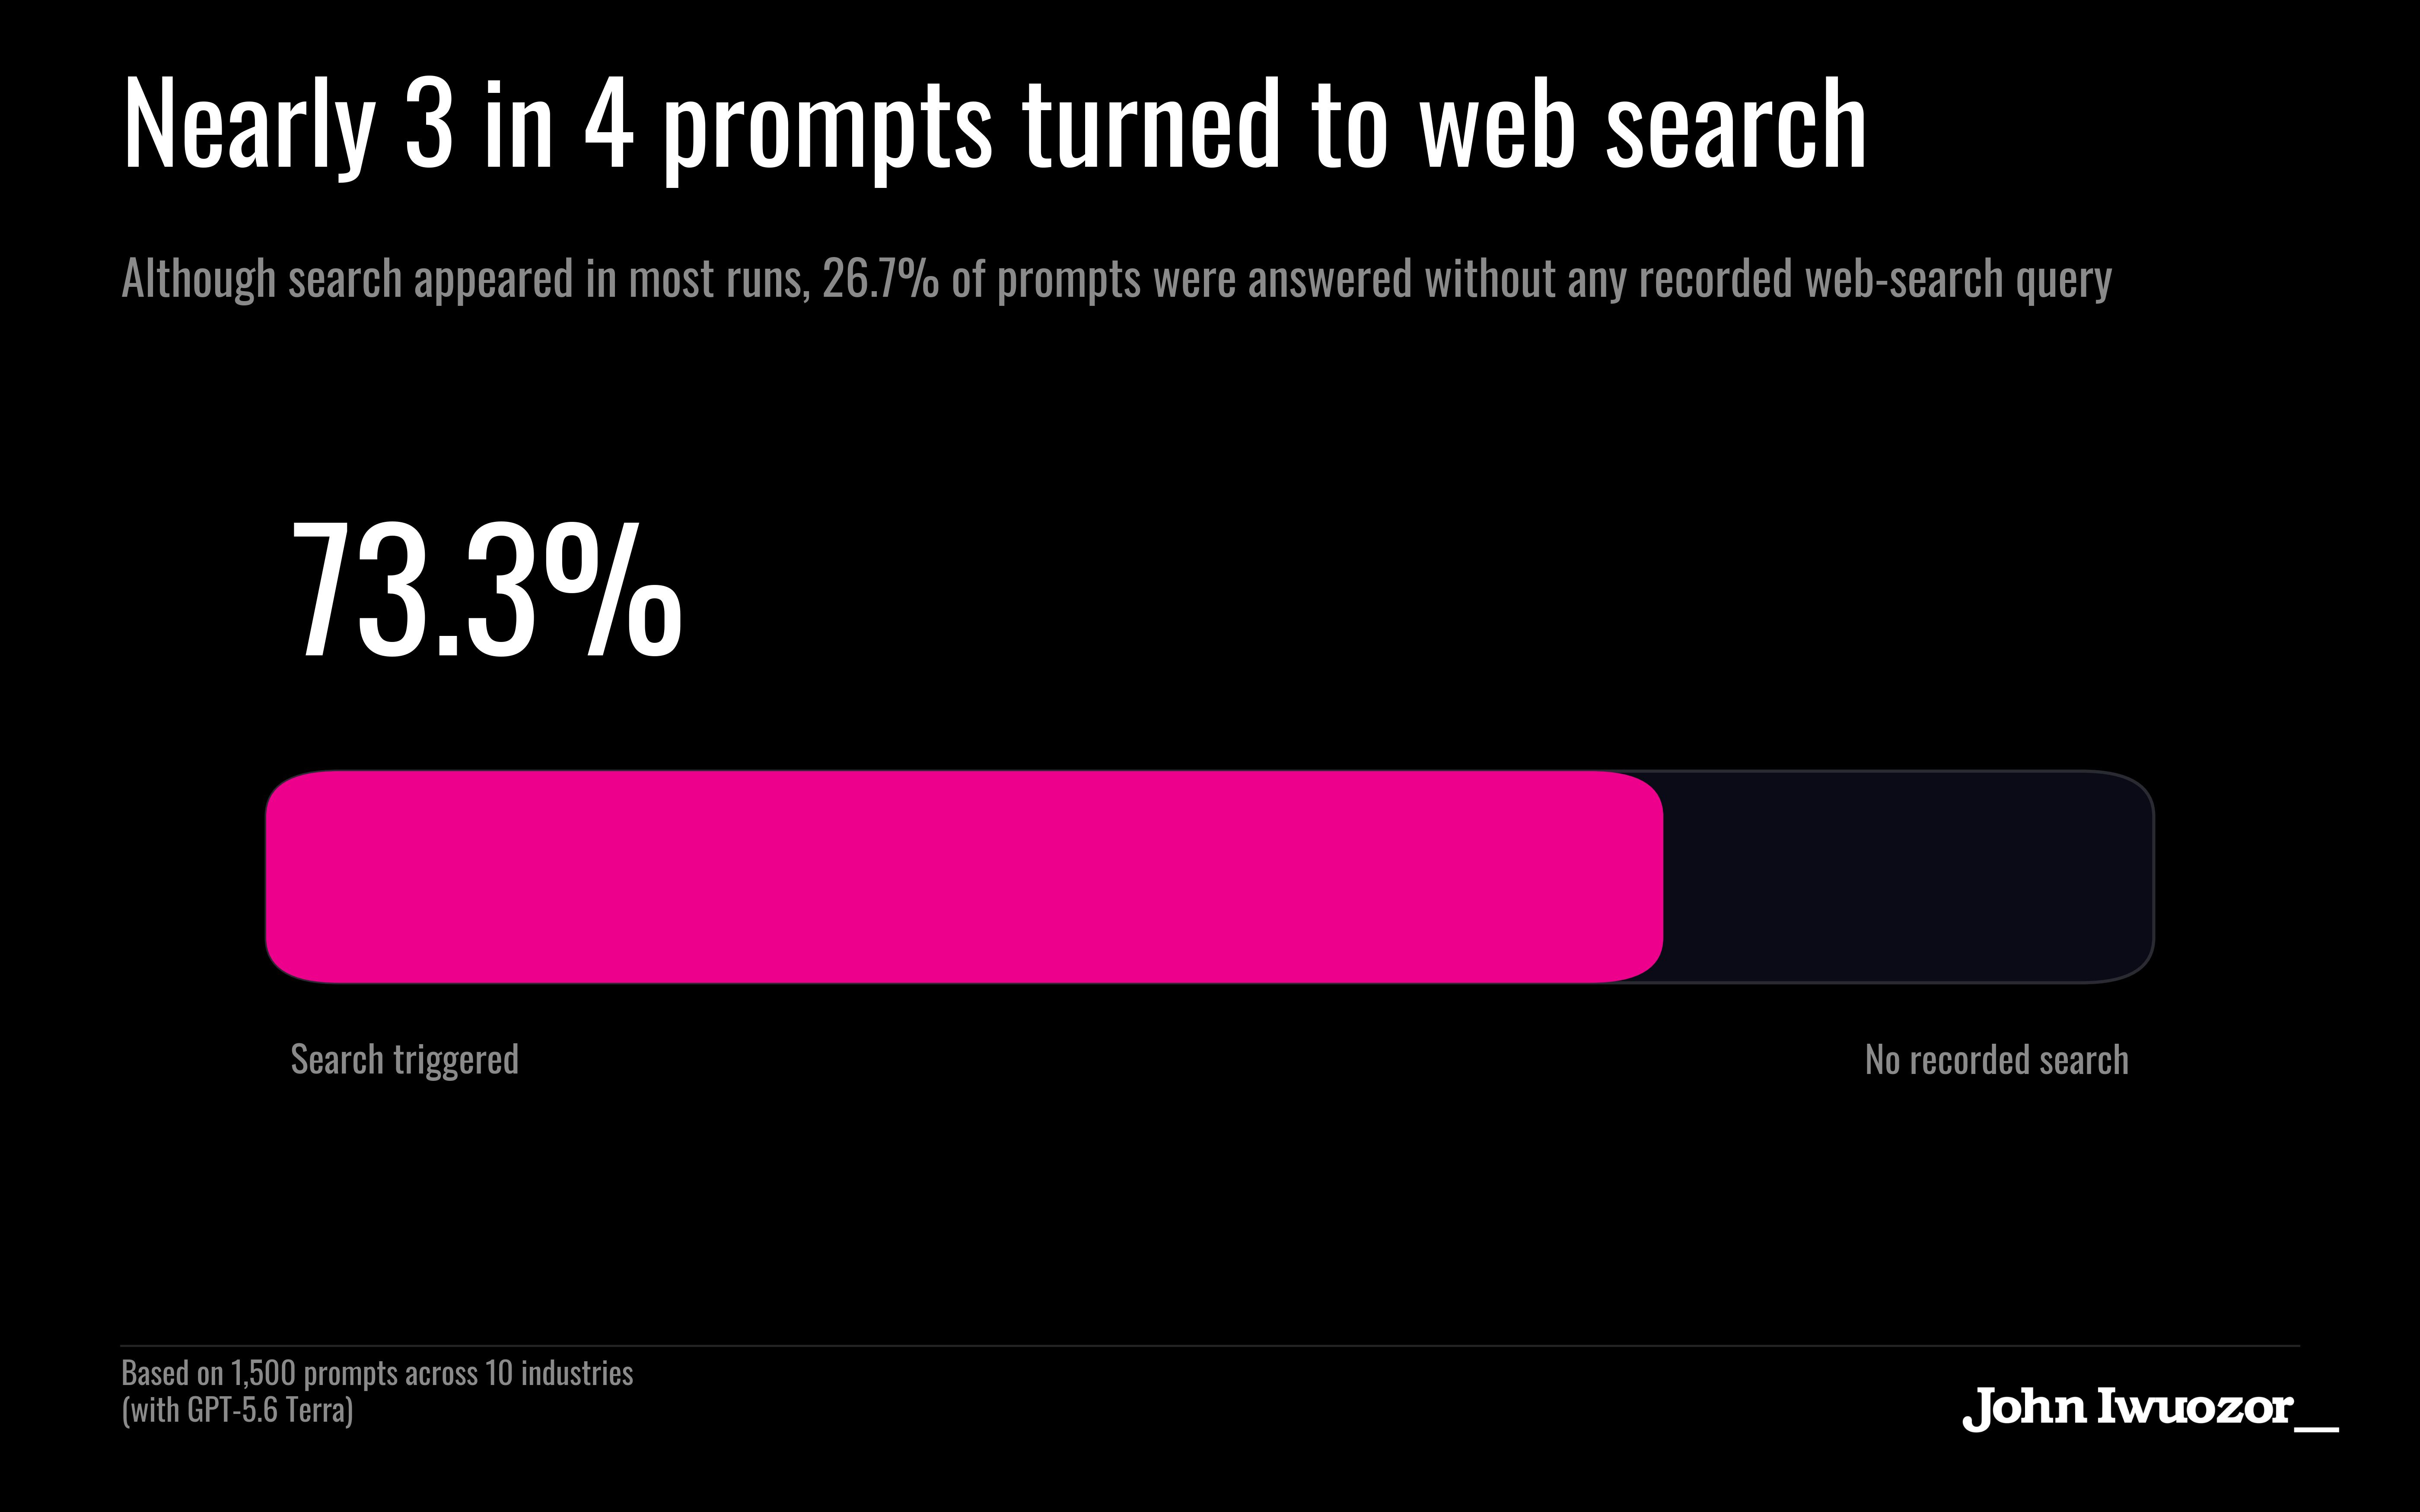
OpenAI’s documentation notes that models can choose whether to use the web-search tool or not. In other words, search is available, but it’s not compulsory. The most likely explanation for non-recorded searches is that the model judged its existing internal knowledge sufficient for those cases.
The contrast between prompt types makes the practical point clearer. A question such as “how to take care of a winter coat long term” can often be answered from stable knowledge. “Best winter coat 2026” however creates a different job: the model now has a reason to look for current products, recent reviews, prices and availability.
This is why it’s counterproductive to treat all prompts equally. Because if a prompt rarely triggers search in the first place, you could have the best content in the world sitting behind it and the model would never go looking; you’re just barking up the wrong tree.
Most Fan-Outs Were Only Three or Four Searches Deep
The term fan-out can make the process sound enormous. That is, one question entering the system and then branching into a large research tree covering every possible interpretation.
That was not the pattern here. Across all prompts, GPT-5.6 generated an average of 3.15 queries per prompt. When you exclude the 400 prompts that did not search, the average rises to 4.29 queries per prompt.
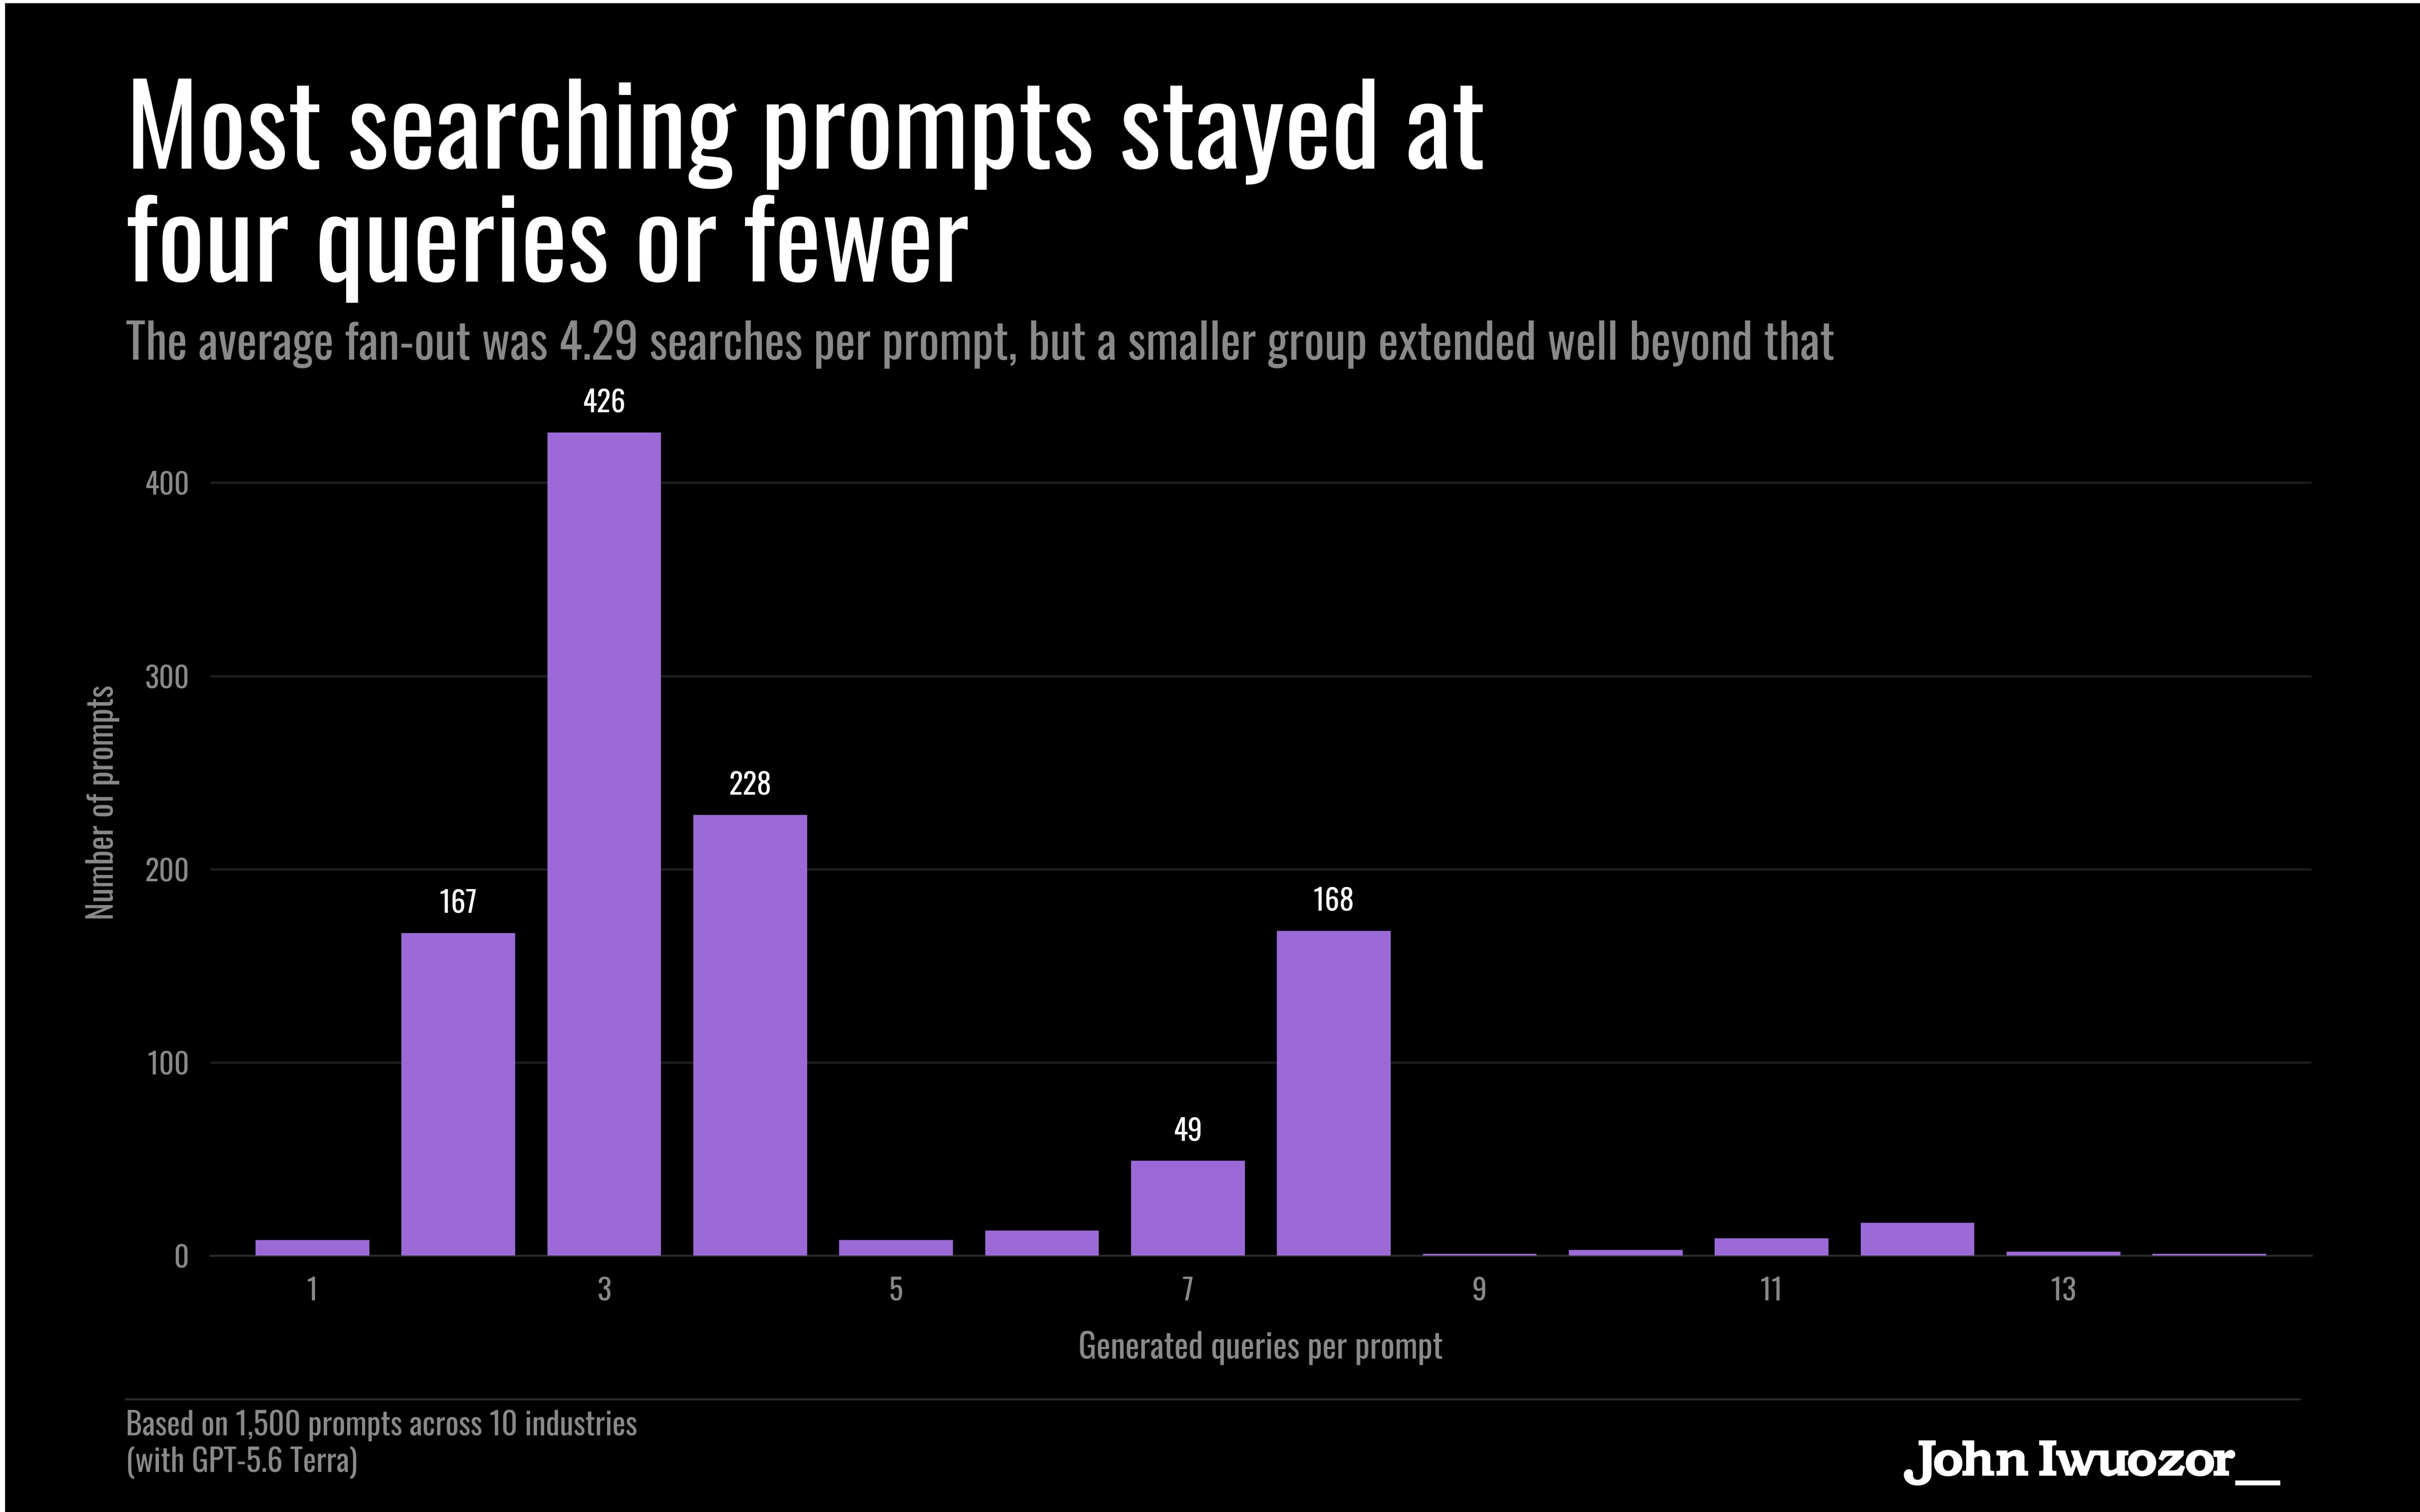
This changes even on an industry-by-industry basis.
Finance Prompts Produced the Deepest Fan-Outs
For example, I noticed that Finance generated the highest average number of queries at 4.23 per prompt. Software followed at 3.69, electronics at 3.66 and automotive at 3.54. Beauty sat at the other end at 2.39.
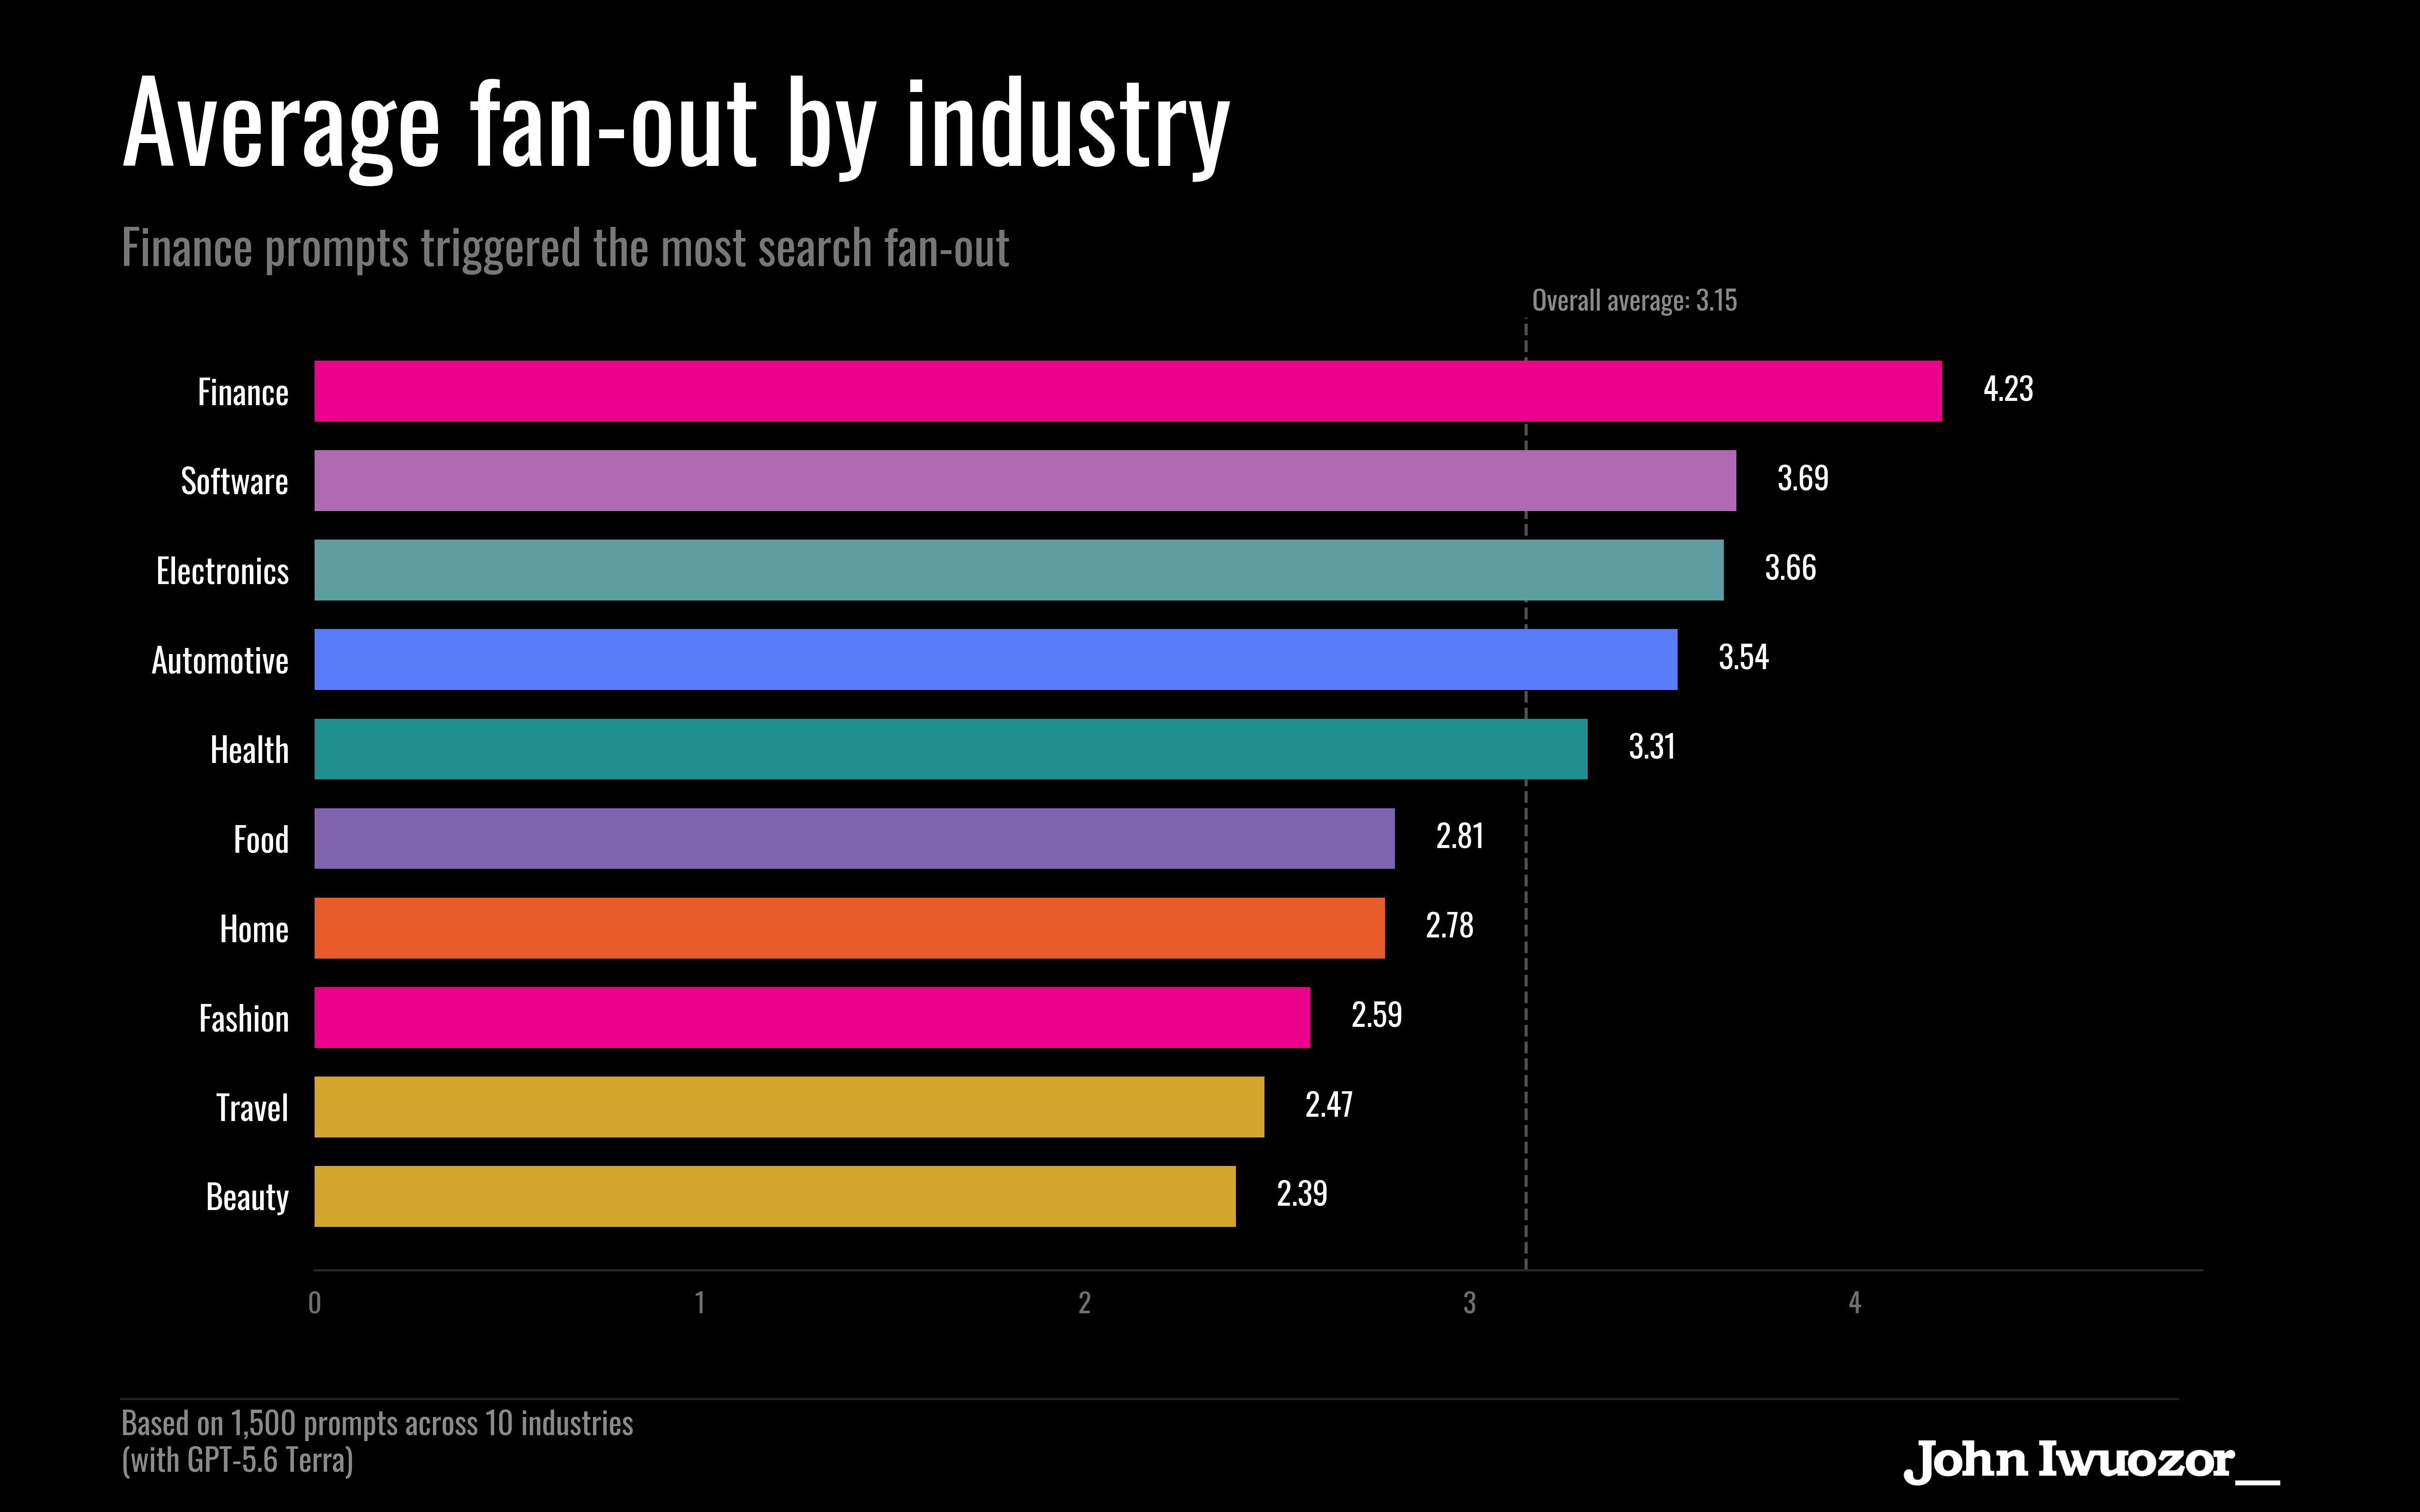
I would not turn this into a blanket claim that finance always forces deeper fan-out. The subcategories matter. My finance set included mortgages, credit cards, savings accounts, insurance and retirement products, all of which naturally invite current rates, fees, regulations and official guidance.
A reasonable hypothesis is that higher-stakes topics encourage more checking. ChatGPT probably tends to carry out more cautious searches for YMYL (“Your Money or Your Life”) topics.
ChatGPT’s Search Process is now Domain-Selective
The clearest pattern in the query data was how often GPT-5.6 restricted searches to particular domains. Across the full dataset, 3,619 of the 4,719 generated queries contained the `site:` operator. That is 76.7%.
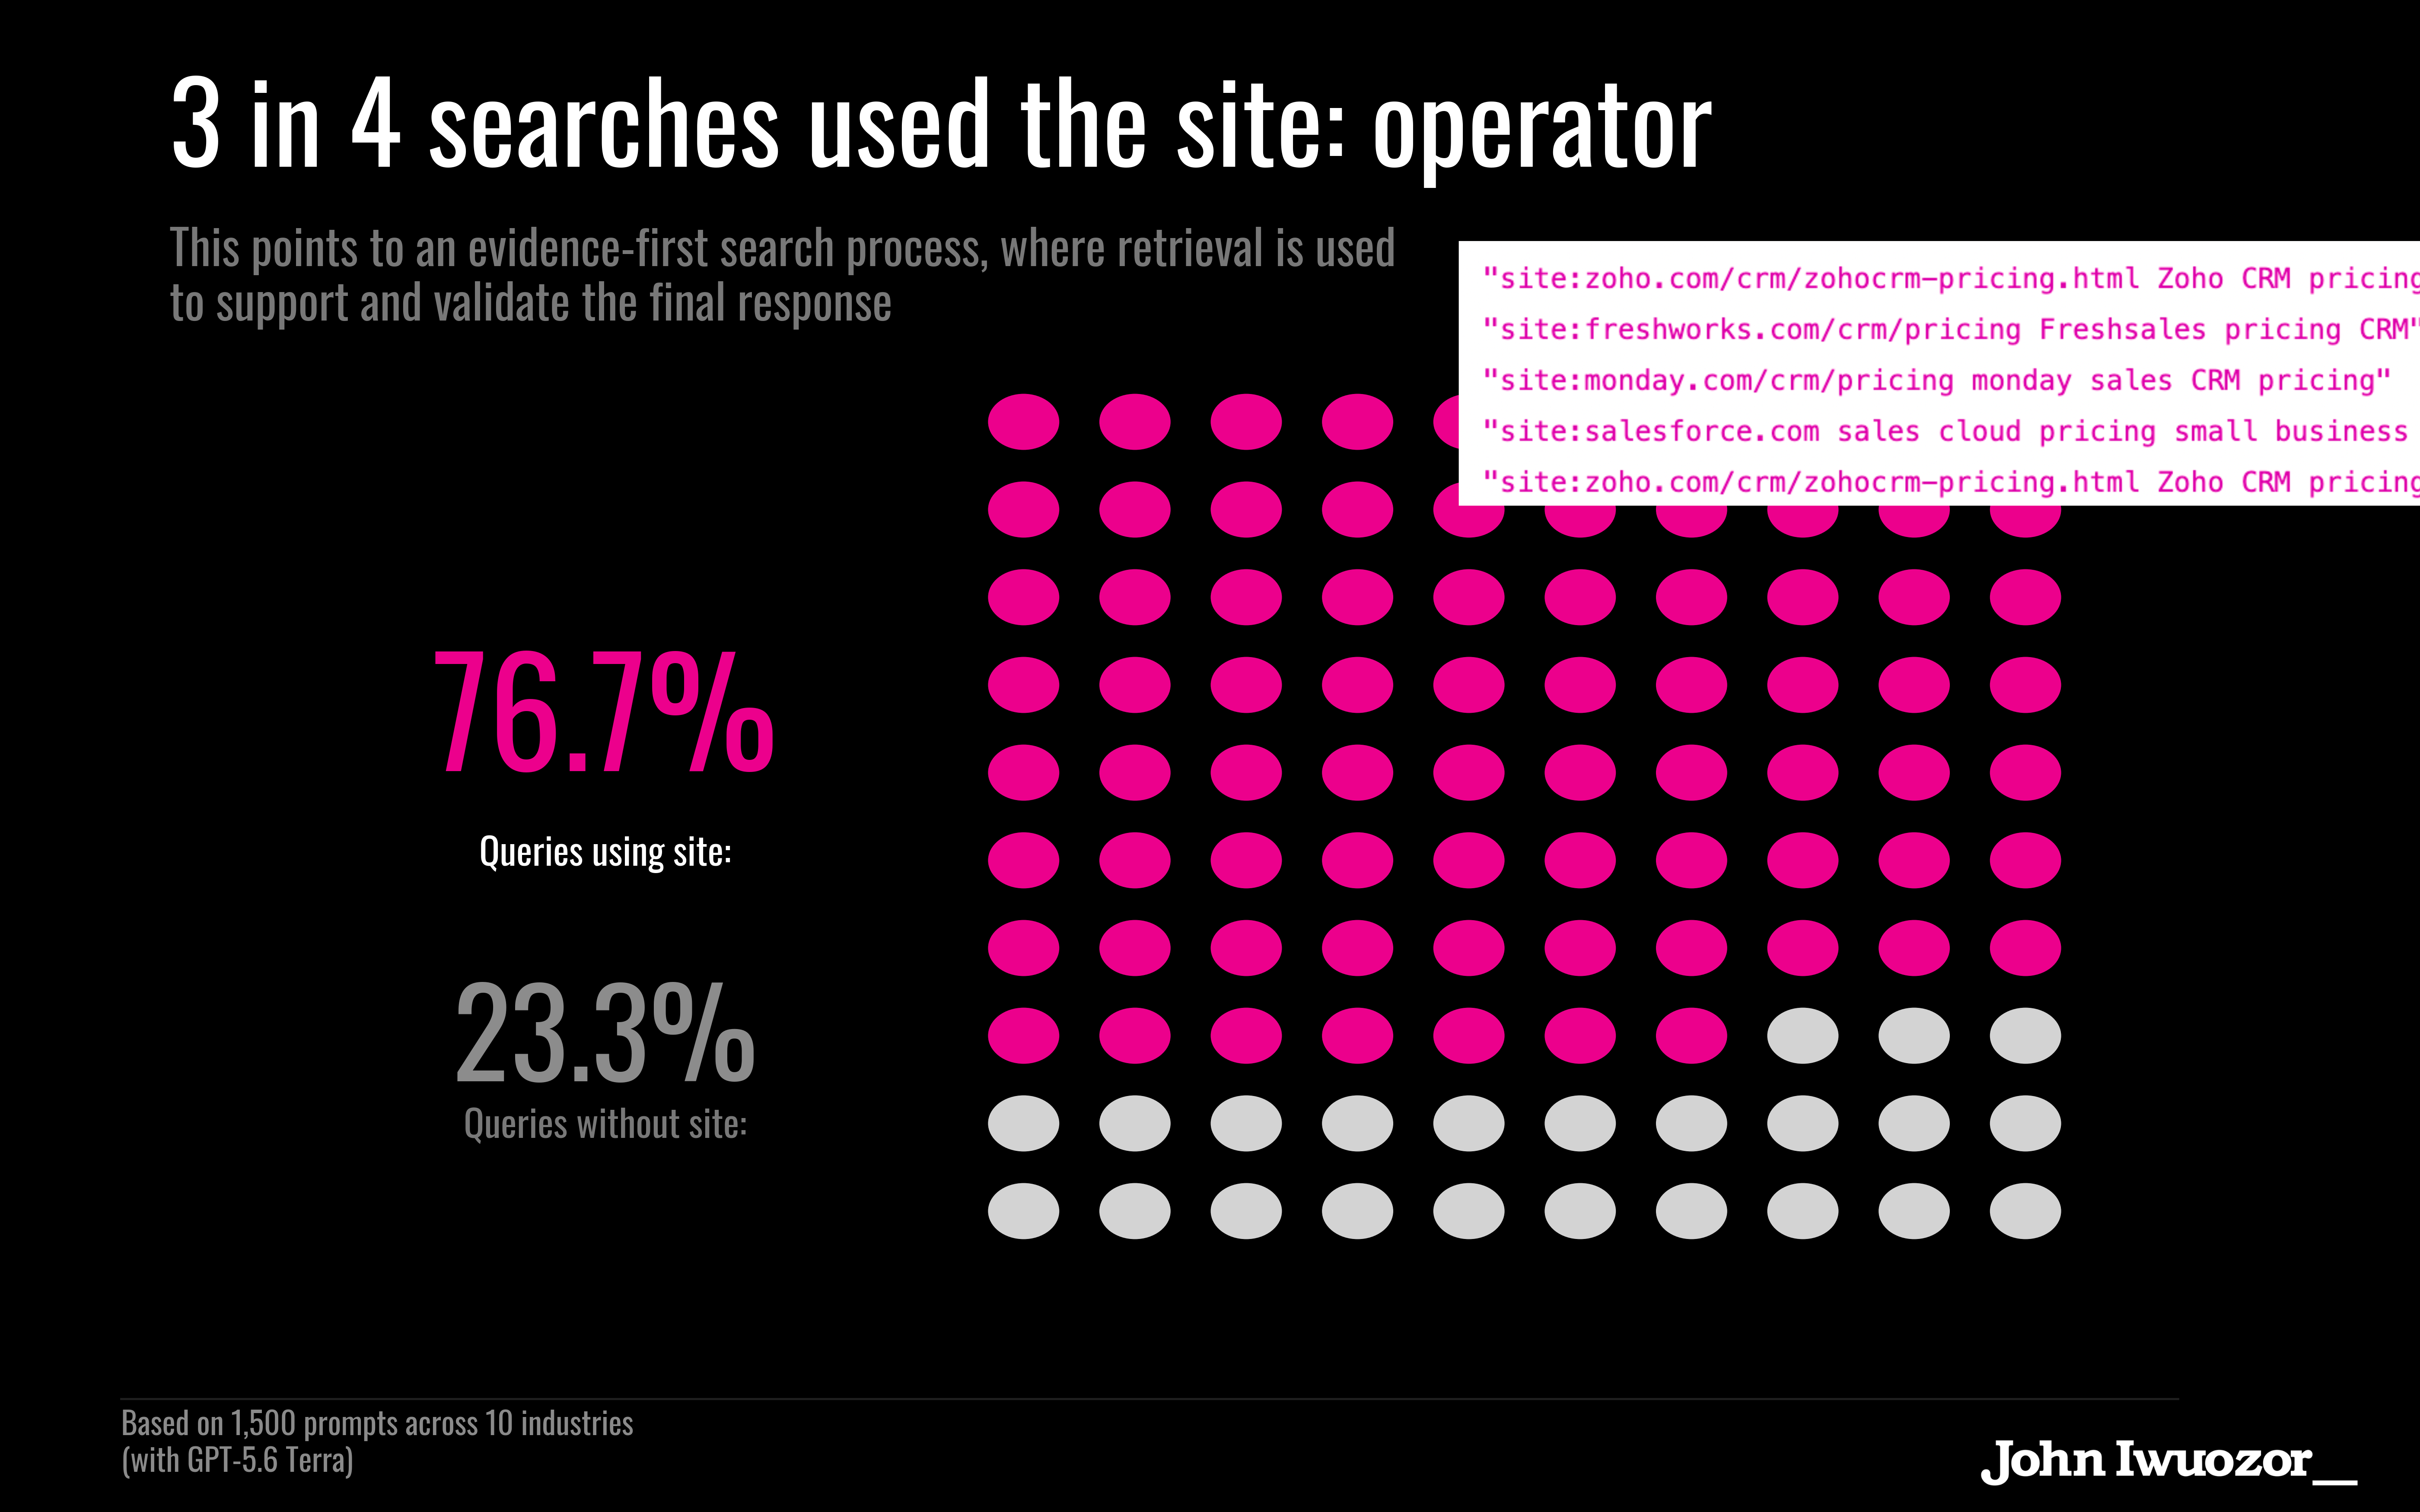
The operator tells the search engine to return pages from a named domain.
An example: a query such as `site:quickbooks.intuit.com pricing QuickBooks Online plans` is not an open search for accounting software. It is a request to find pricing information inside QuickBooks’ own website.
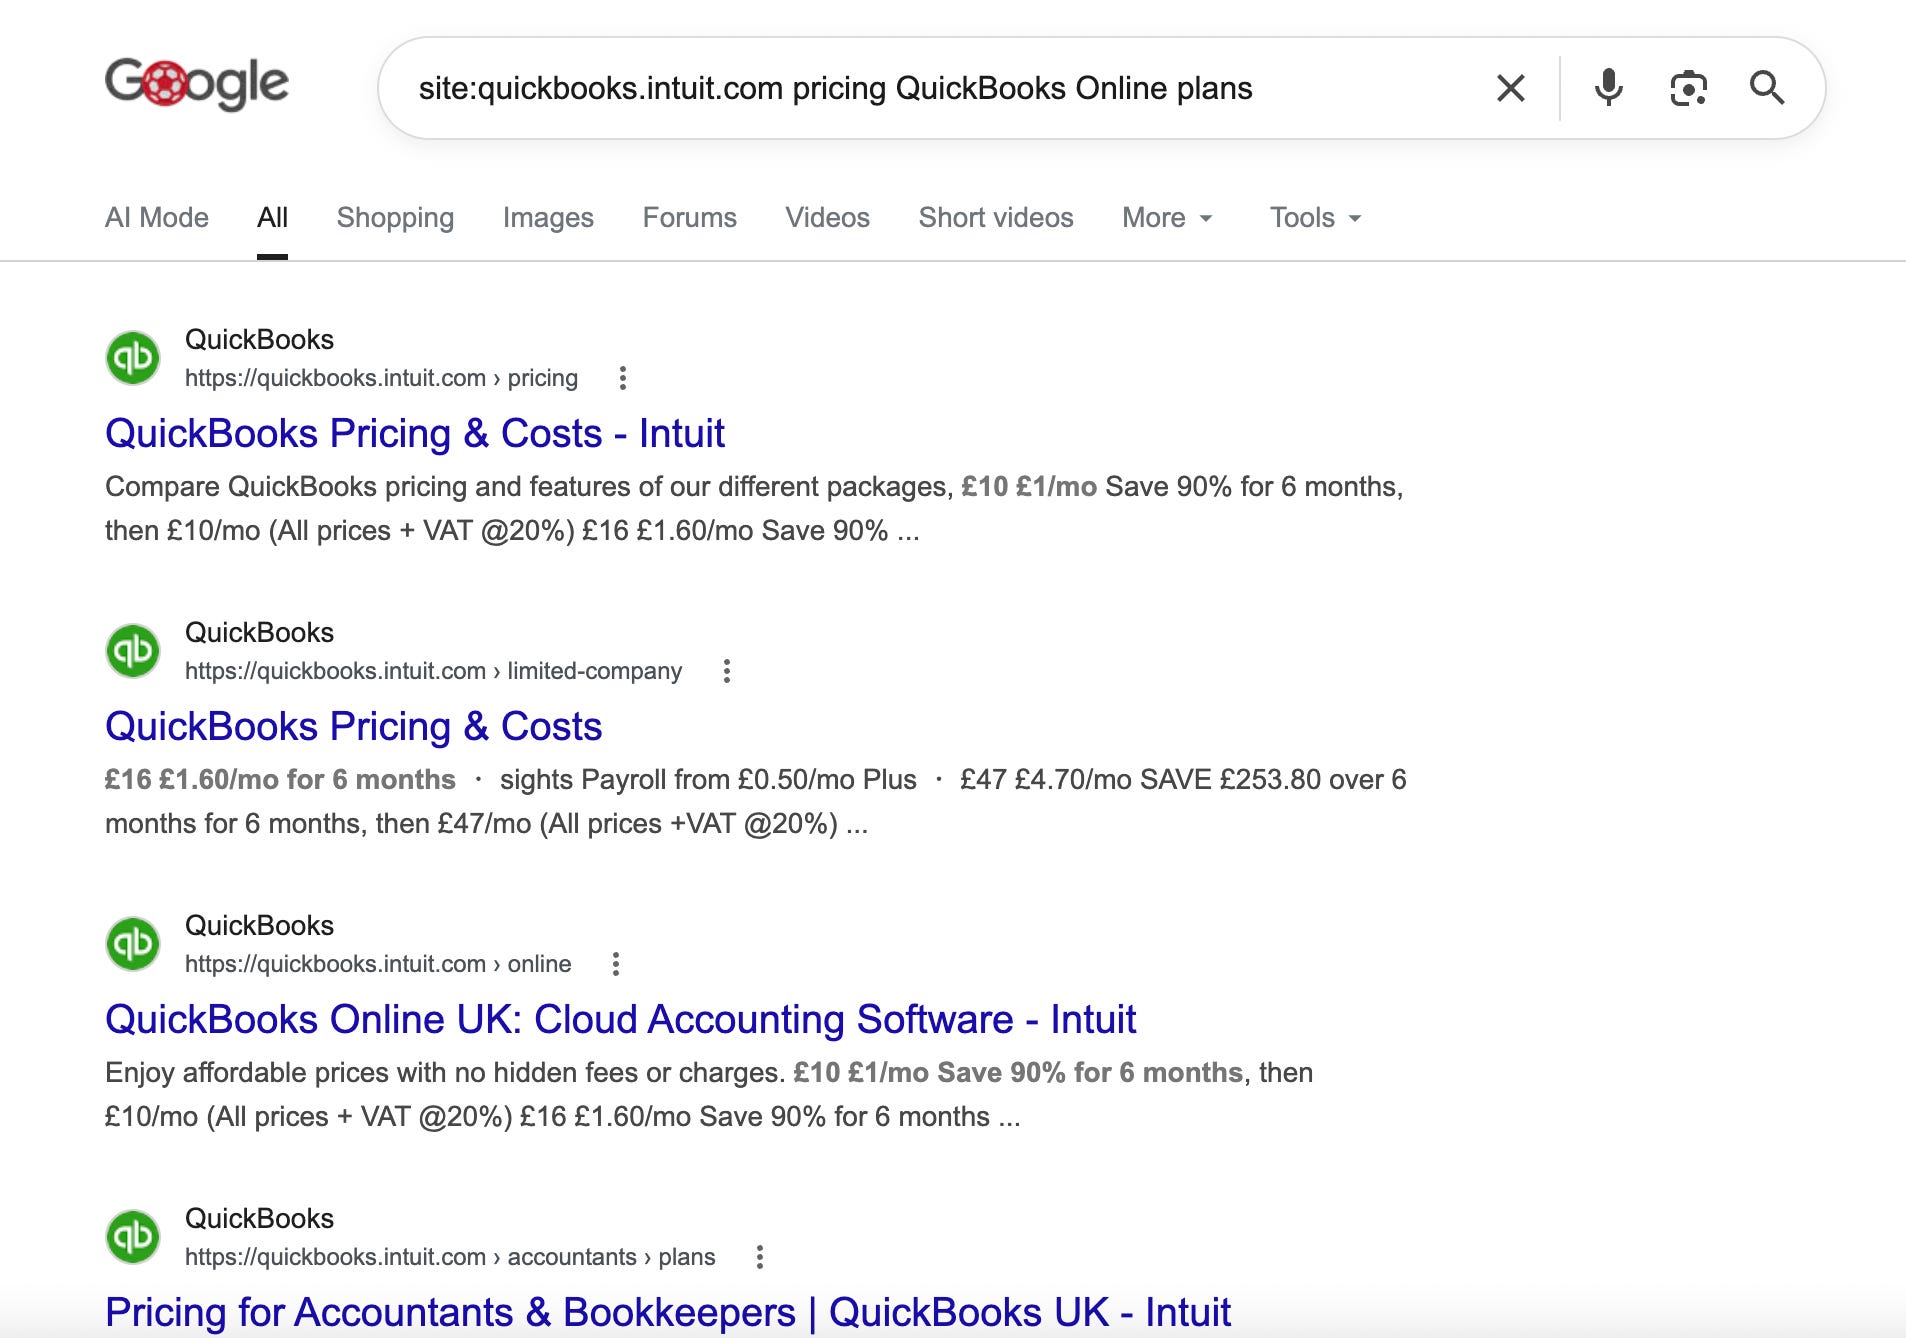
This changes how we think about fan-out in ChatGPT.
A large share of these searches were not broad attempts to discover every possible source. They were targeted retrieval actions aimed at websites the model had already chosen to inspect.
This might sound crazy but at this stage, you’re not just competing with appearing for any particular query. Your brand also has to become one of the domains ChatGPT considers worth checking directly. How do you make that shortlist? That remains unclear, although I have some theories later in this piece.
And this whole brouhaha is not confined to one industry. Explicit `site:` usage appears consistently across verticals:
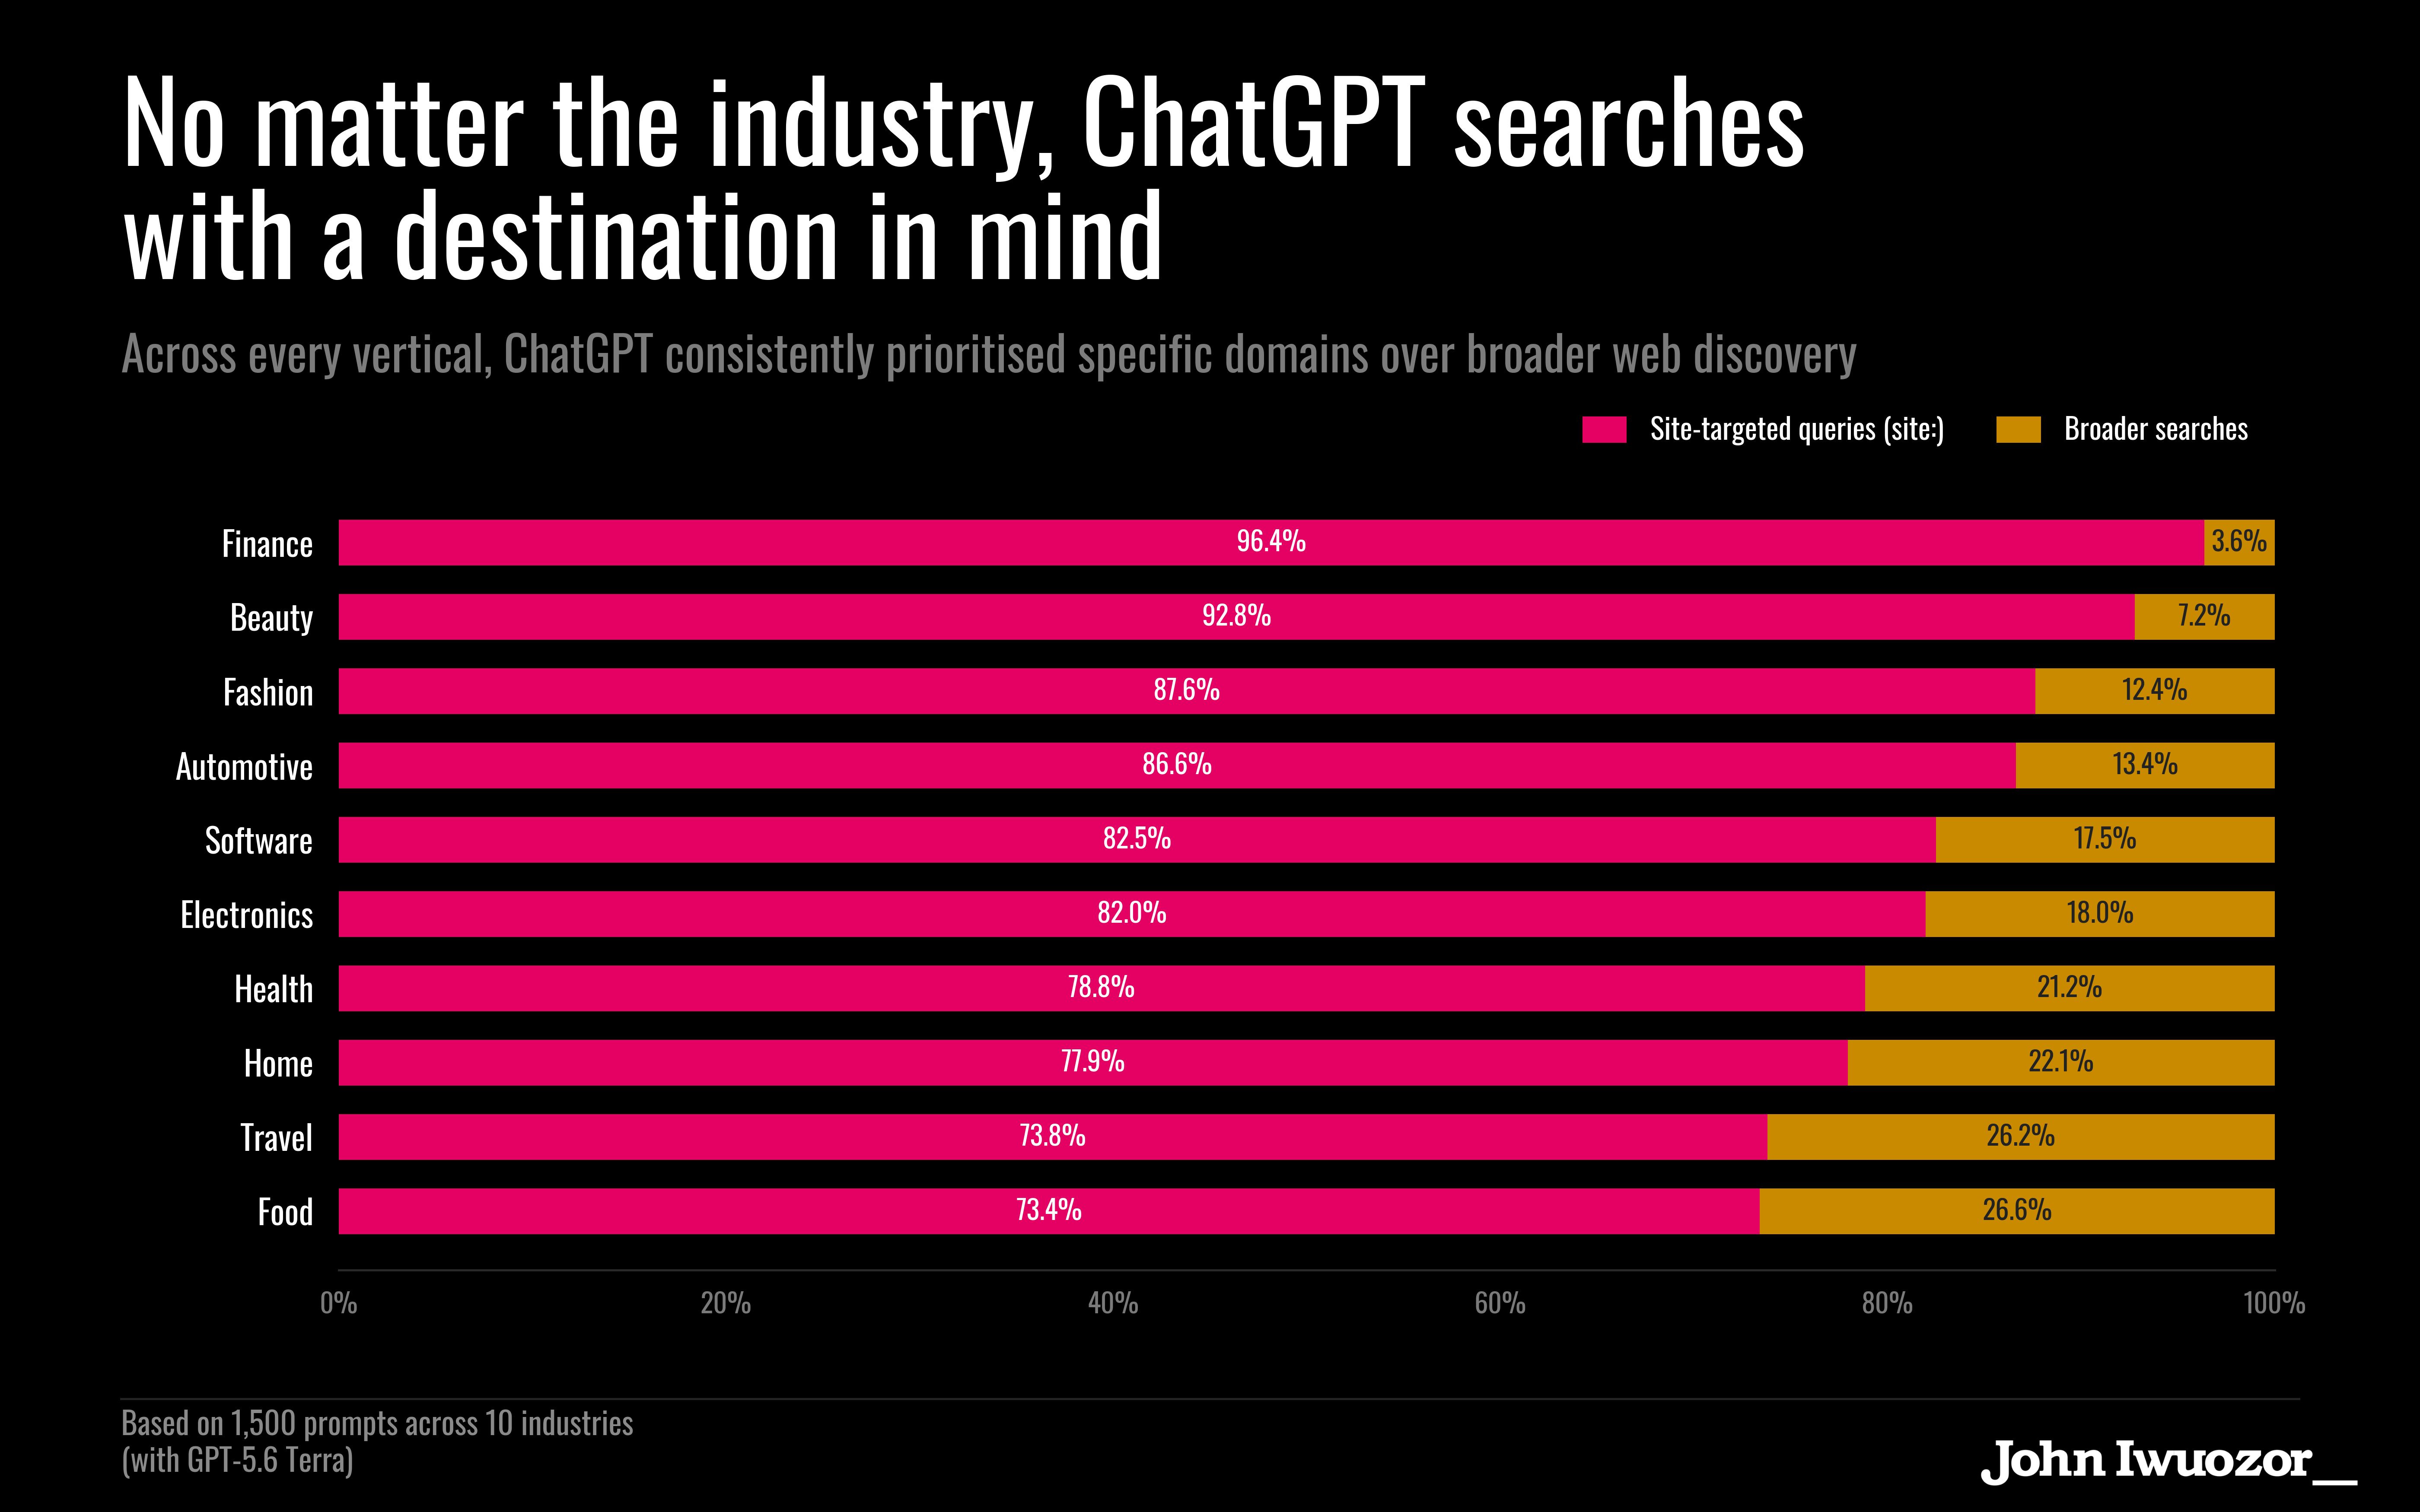
Another important detail I noticed was that ChatGPT often searched broadly first, then narrowed to official sites. This happened a lot among my freshness prompts.
A typical sequence looked like this: start with a broad market search → identify plausible options→ then check individual brands for prices, features or official documentation.
There are numerous examples in my dataset, but here is a good one:
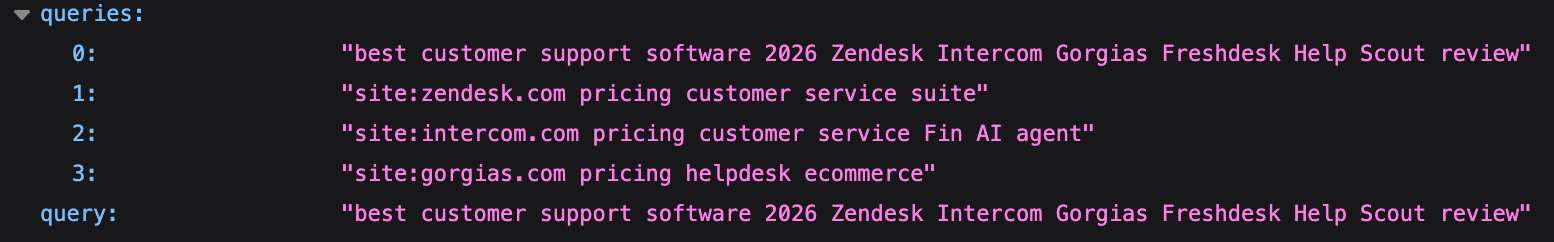
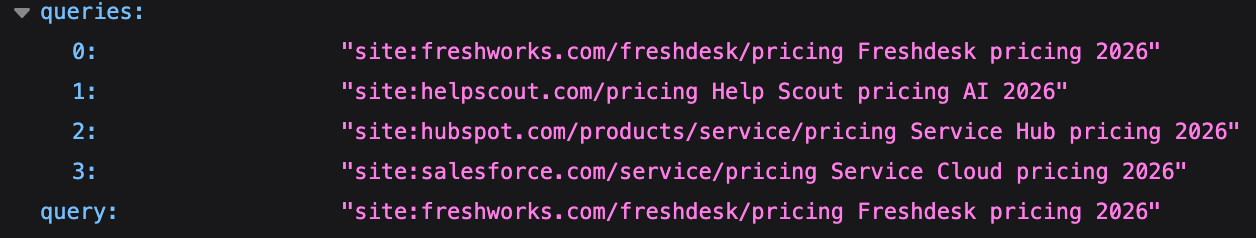
The customer-support-software example in the raw JSON moves from a broad search naming several providers to direct pricing checks across Freshdesk, Help Scout, HubSpot and Salesforce.
My interpretation here is that discovery and verification are operating as separate stages (in some cases). I see it this way for brands:
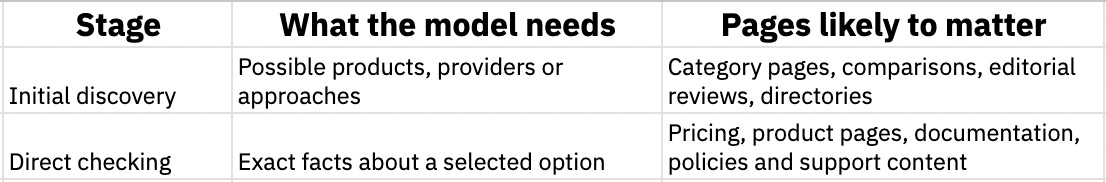
While third-party coverage may help you enter the candidate set, your own website needs to give the model clean, current facts when it comes looking for proof.
More Searching Did Not Necessarily Produce Longer Answers
Before running the experiment, I expected deeper retrieval to produce longer responses. But I quickly found that more query searches ≠ more word count.
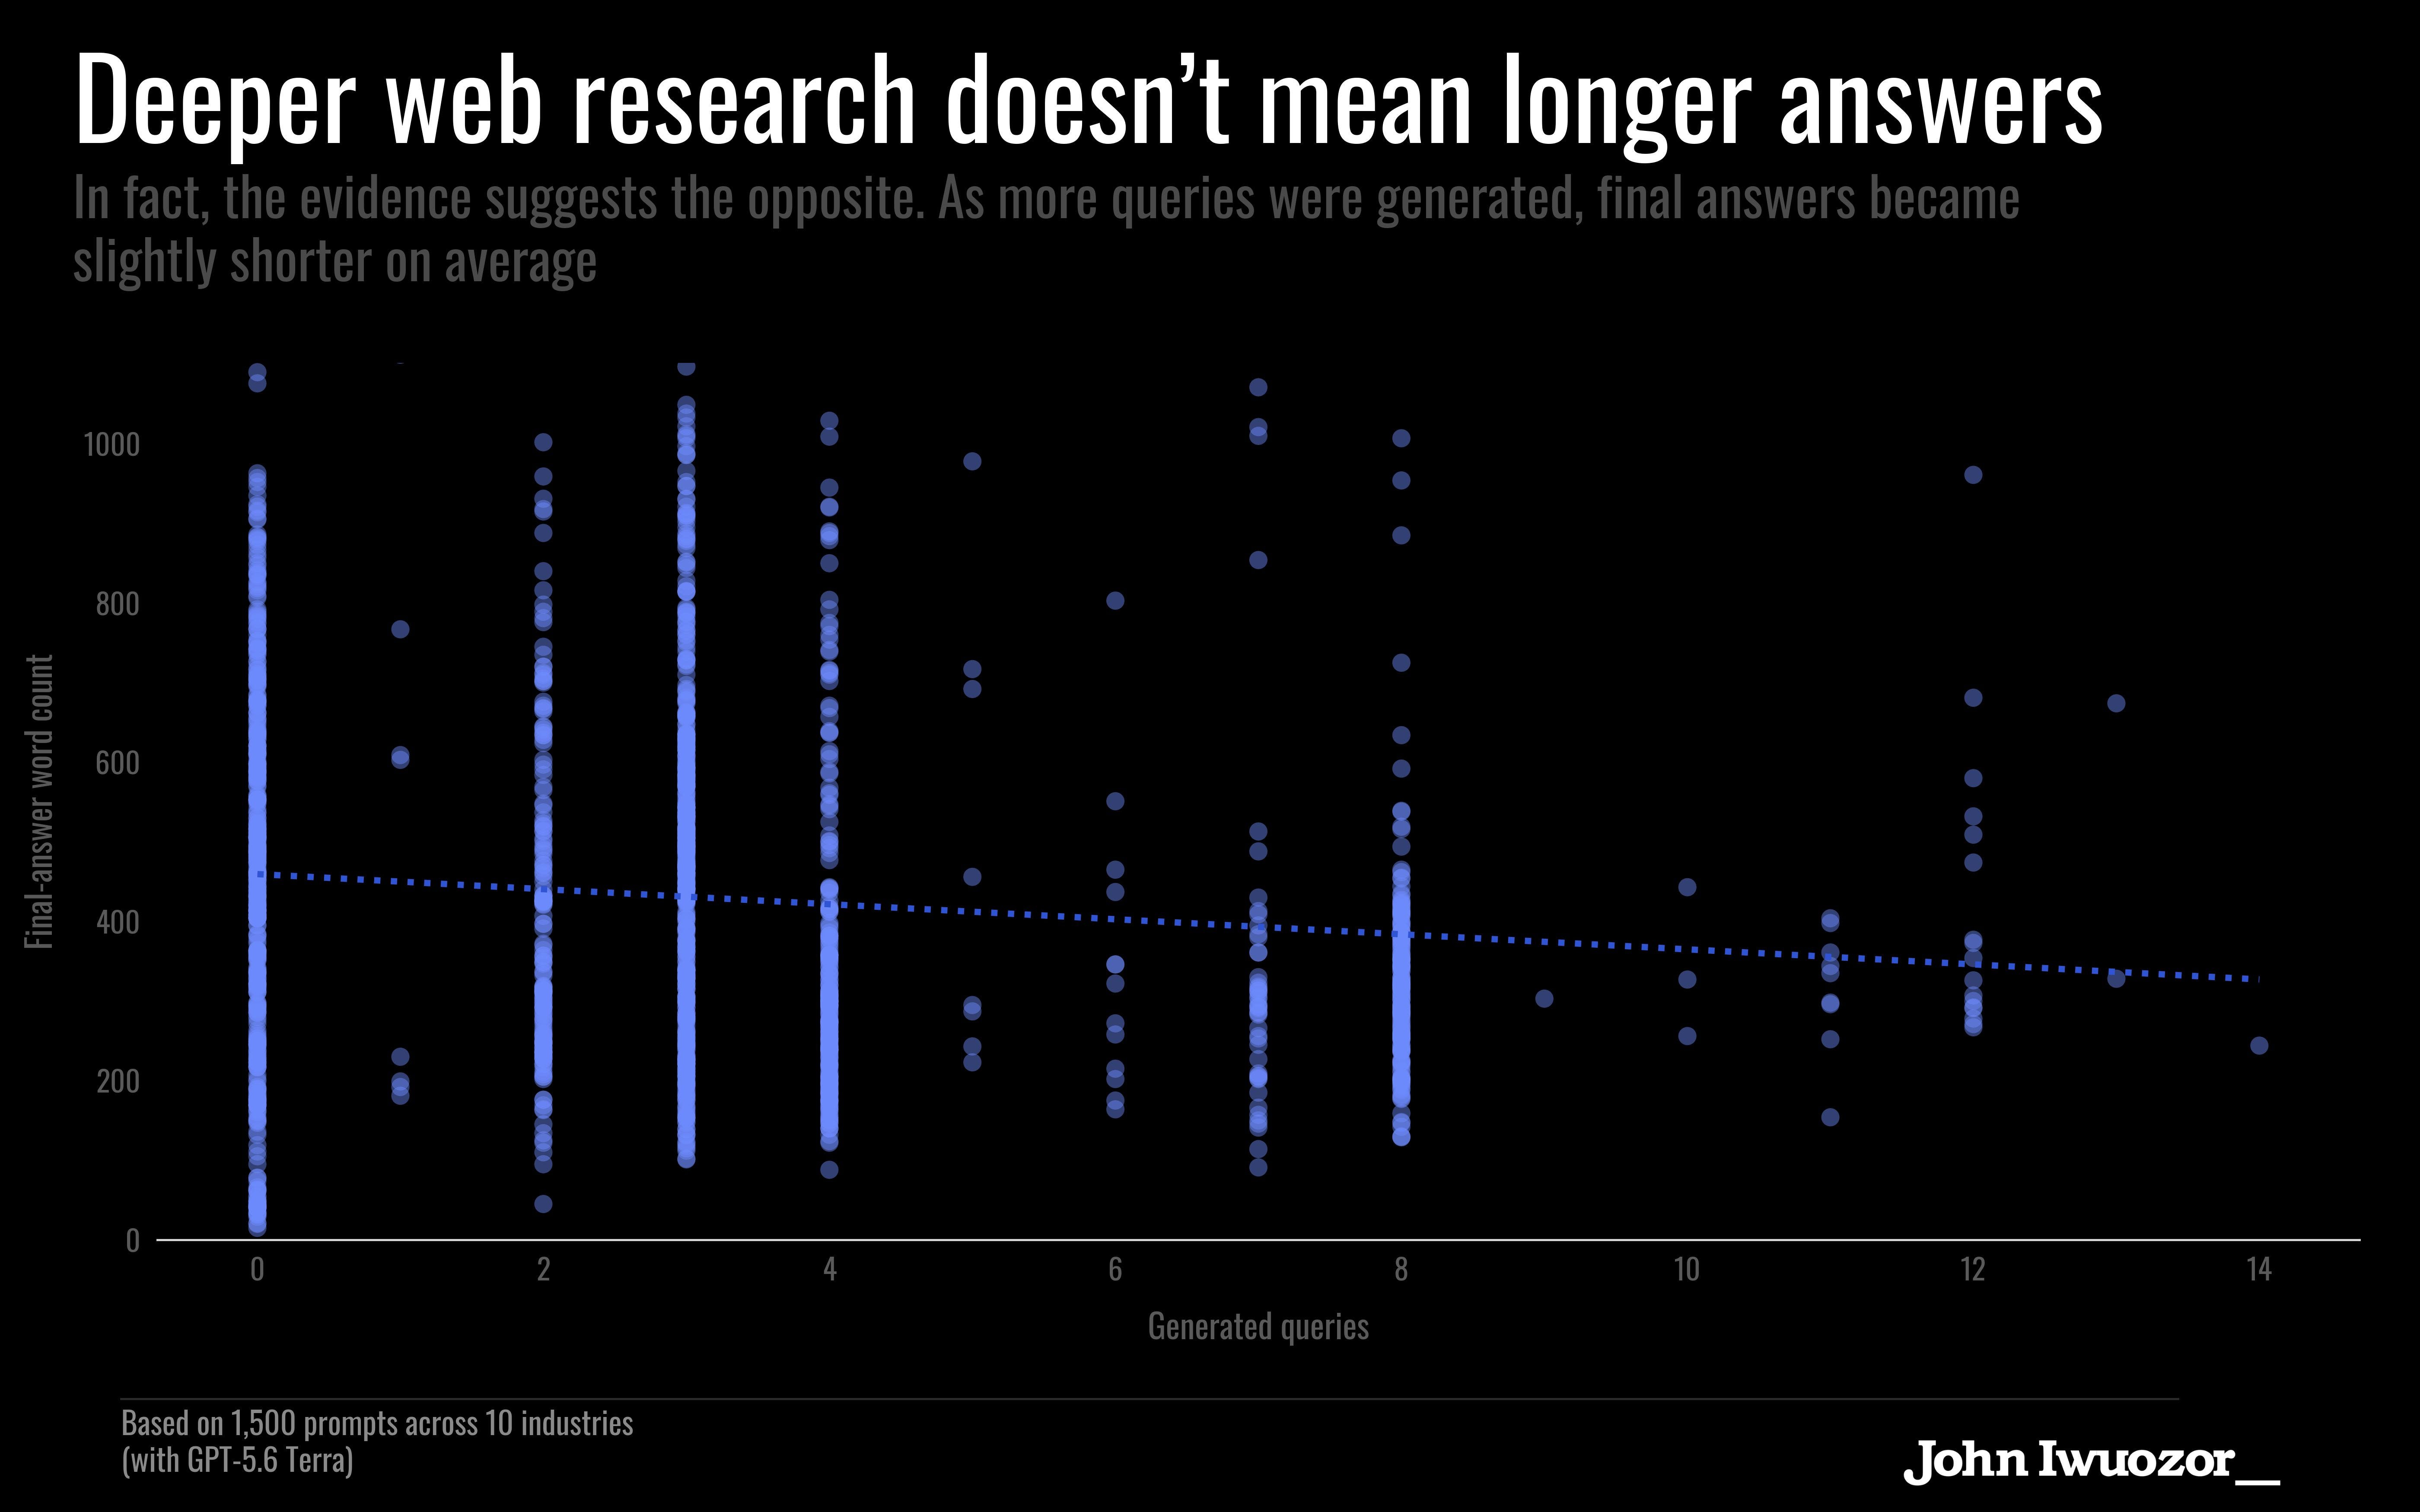
This data definitely shows that visible answer length is a poor way to estimate how much retrieval happened behind the scenes.
Here’s my hypothesis: That extra retrieval may be helping the model confirm a price, rule out an alternative or resolve a detail rather than giving it more material to write about. Another one is GPT-5.6 being more concise by default than the previous model according to documentation.
A Typical Answer Barely Breaks 400 Words
Still on the topic of answers, the average response across the full dataset contained 433 words and 3,161 characters.
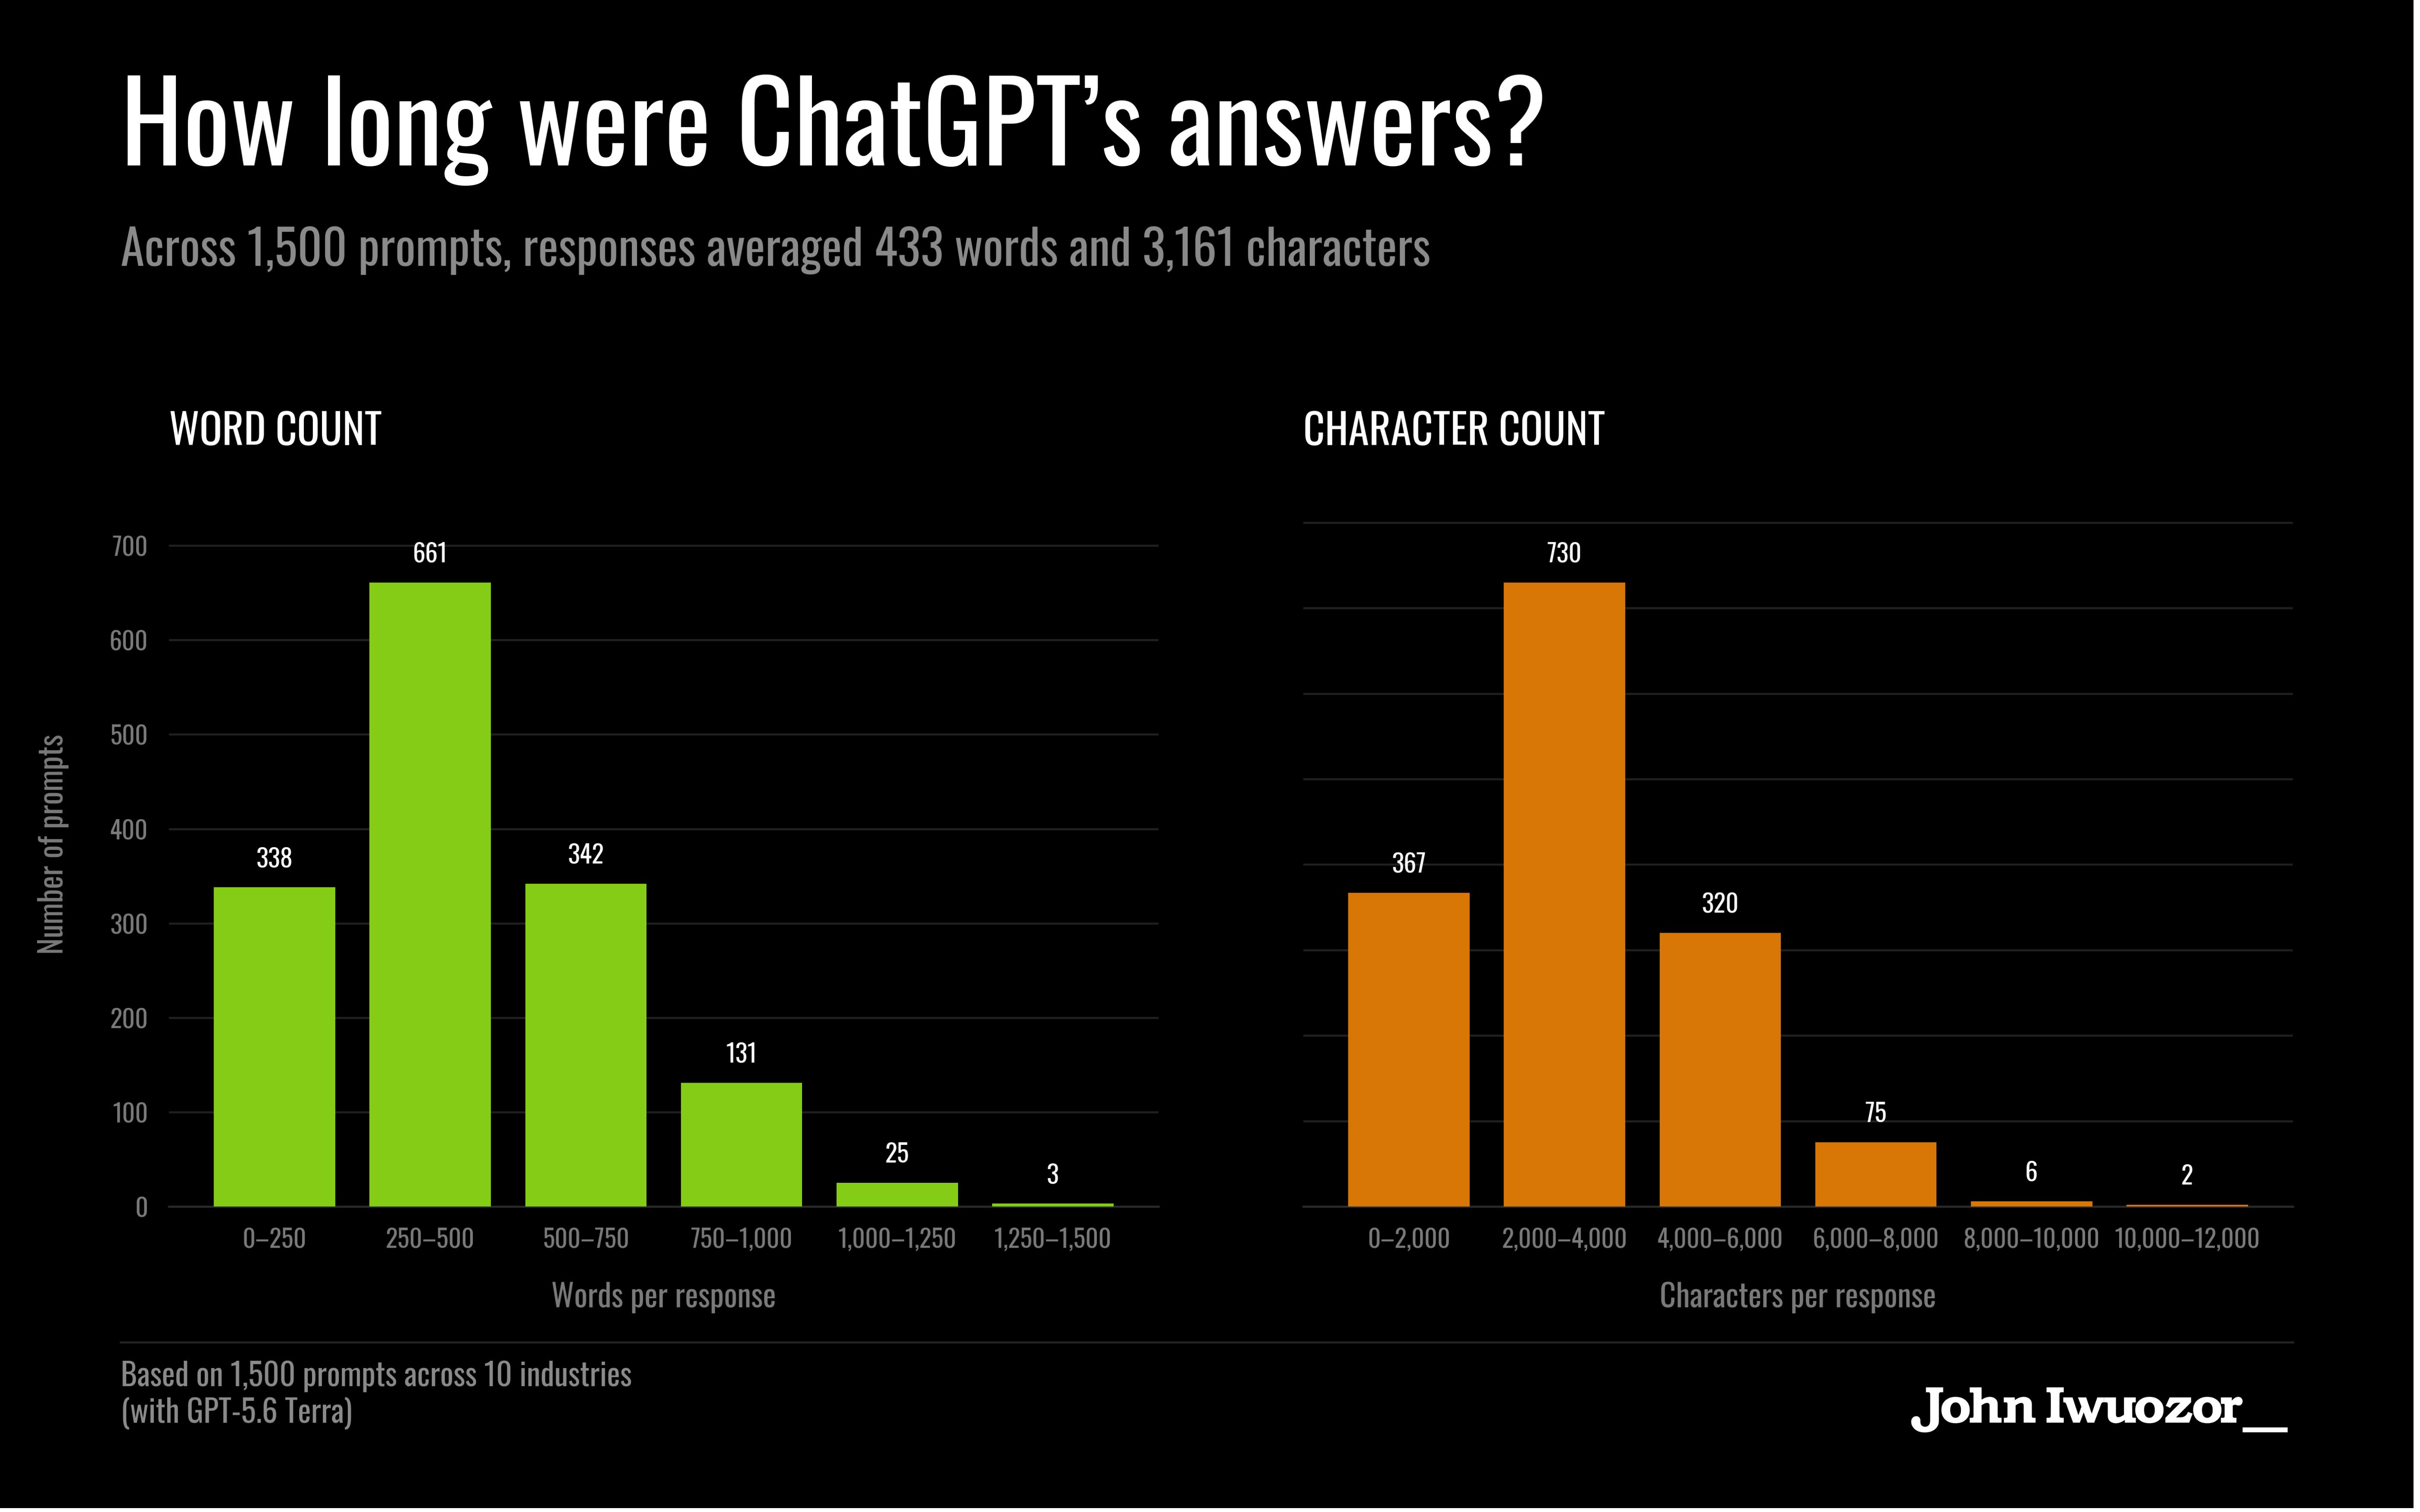
Most responses fell between 250 and 500 words, although there was a meaningful group between 500 and 750 words. Only a small number exceeded 1,000 words.
Interestingly, this is close to the findings of a recent Profound study called the Parrot Problem. Profound analysed 50,000 prompts and reported that ChatGPT responses averaged 3,043 characters, compared with 2,921 for Gemini and 1,590 for Claude. My Terra dataset averaged 3,161 characters.
The two studies are not directly comparable, but they point in the same direction: ChatGPT’s default answers are already fairly substantial.
That gives the model enough room to introduce several products, claims, caveats and sources without necessarily sending the user anywhere else. It explains why generic informational pages may feel more exposed than they did in a ten-blue-links world.
ChatGPT Builds Its Own Search Vocabulary
This was another interesting insight I got while analysing the behaviour of queries. ChatGPT appears to use a distinct search vocabulary when answering different kinds of questions.
To show you what I mean, I extracted unigrams, bigrams and trigrams from the 4,719 query strings, then manually reviewed them by prompt type to remove noise.
The final vocabulary chart uses recurring terms and phrases that made sense for the job implied by the prompt.
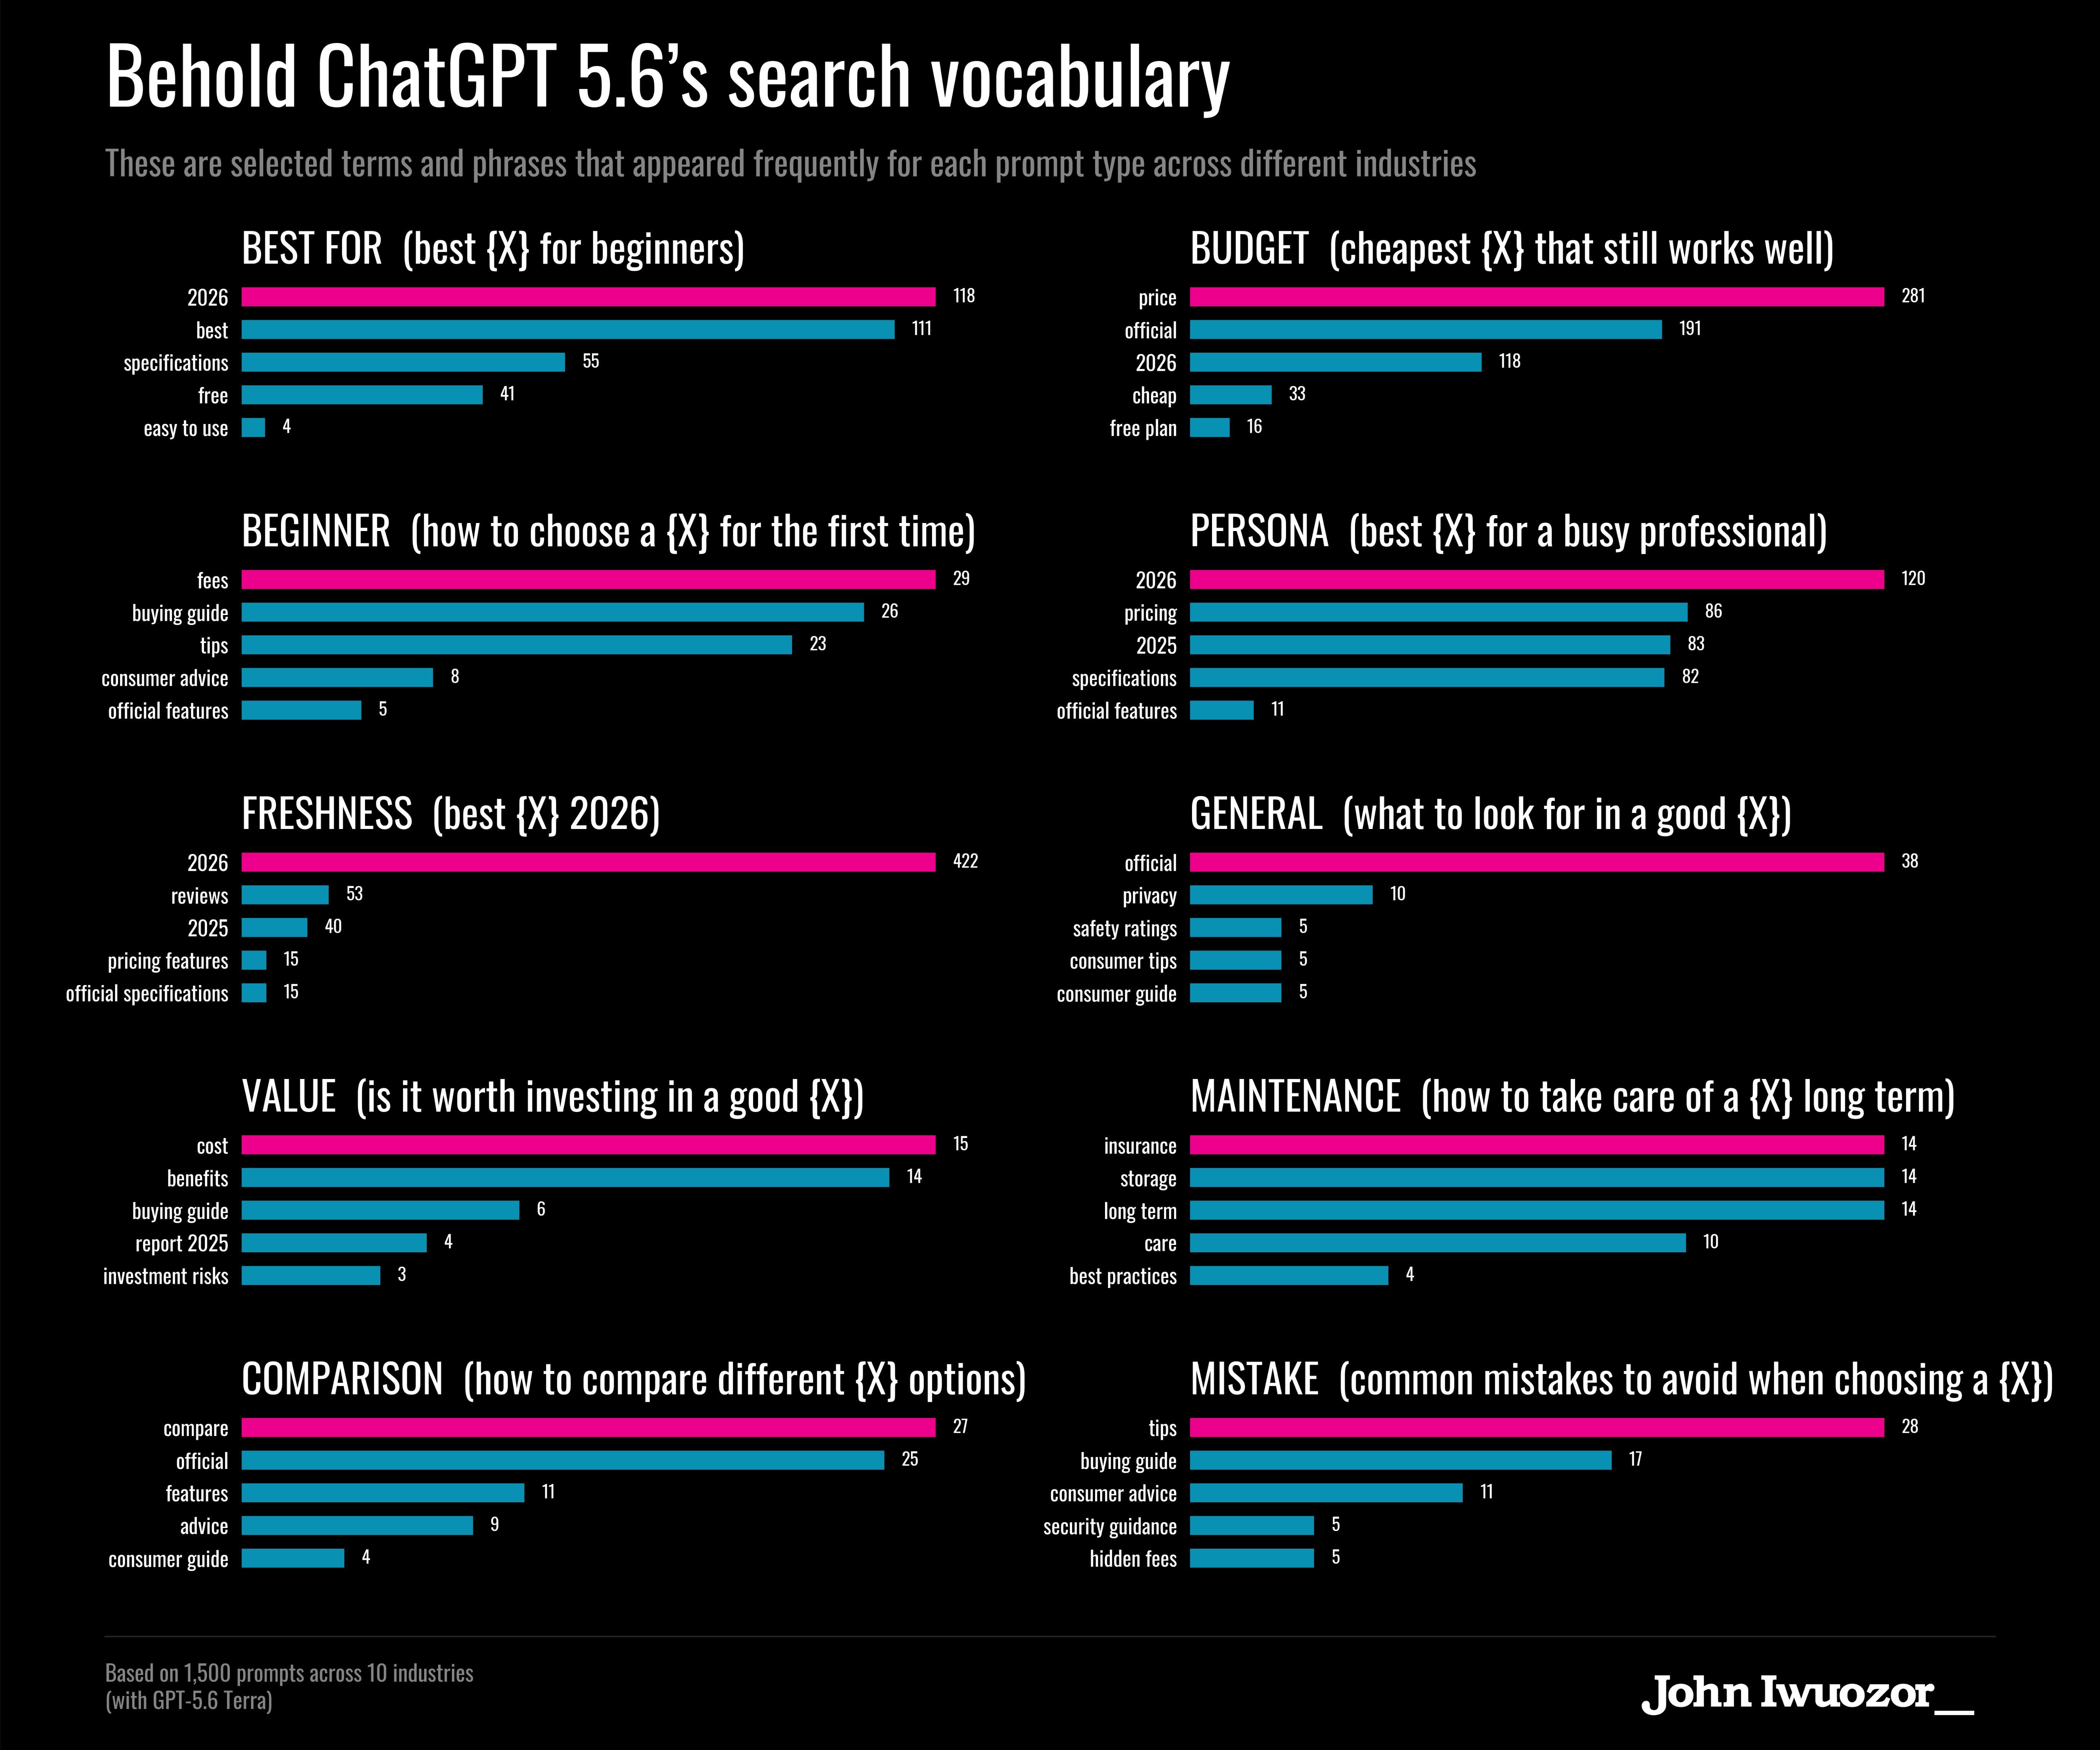
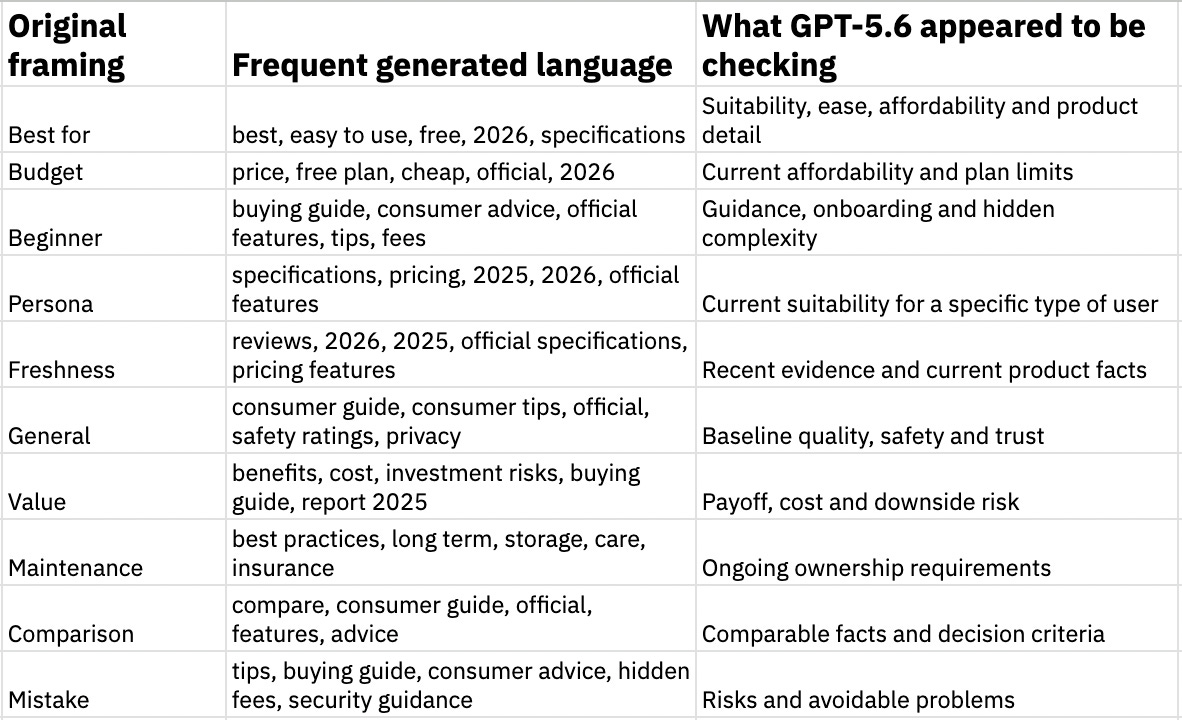
The pattern is easy to miss if you only track the original prompt. A person asks for one recommendation, but the search process turns it into several smaller evidence requirements:
What does it cost?
Is there a free version?
What is included at that price?
Are there hidden fees?
Is the information current?
What does the official site say?
Do third-party reviews support the recommendation?
This is food for thought, especially for content marketing teams in B2B companies. AI is aggregating information from product pages and looking for evidence. That’s the key word here. Site preparedness matters more than forcing every answer into one mega-page.
ChatGPT Repeatedly Added Evidence-Oriented Modifiers
When I grouped common words and close variants across all generated searches, the same types of modifiers kept appearing.
Pricing language was the largest group, with price and pricing appearing 920 times. References to 2025 and 2026 followed at 704, while fees, guidance, specifications, features, reviews and safety language also appeared repeatedly.
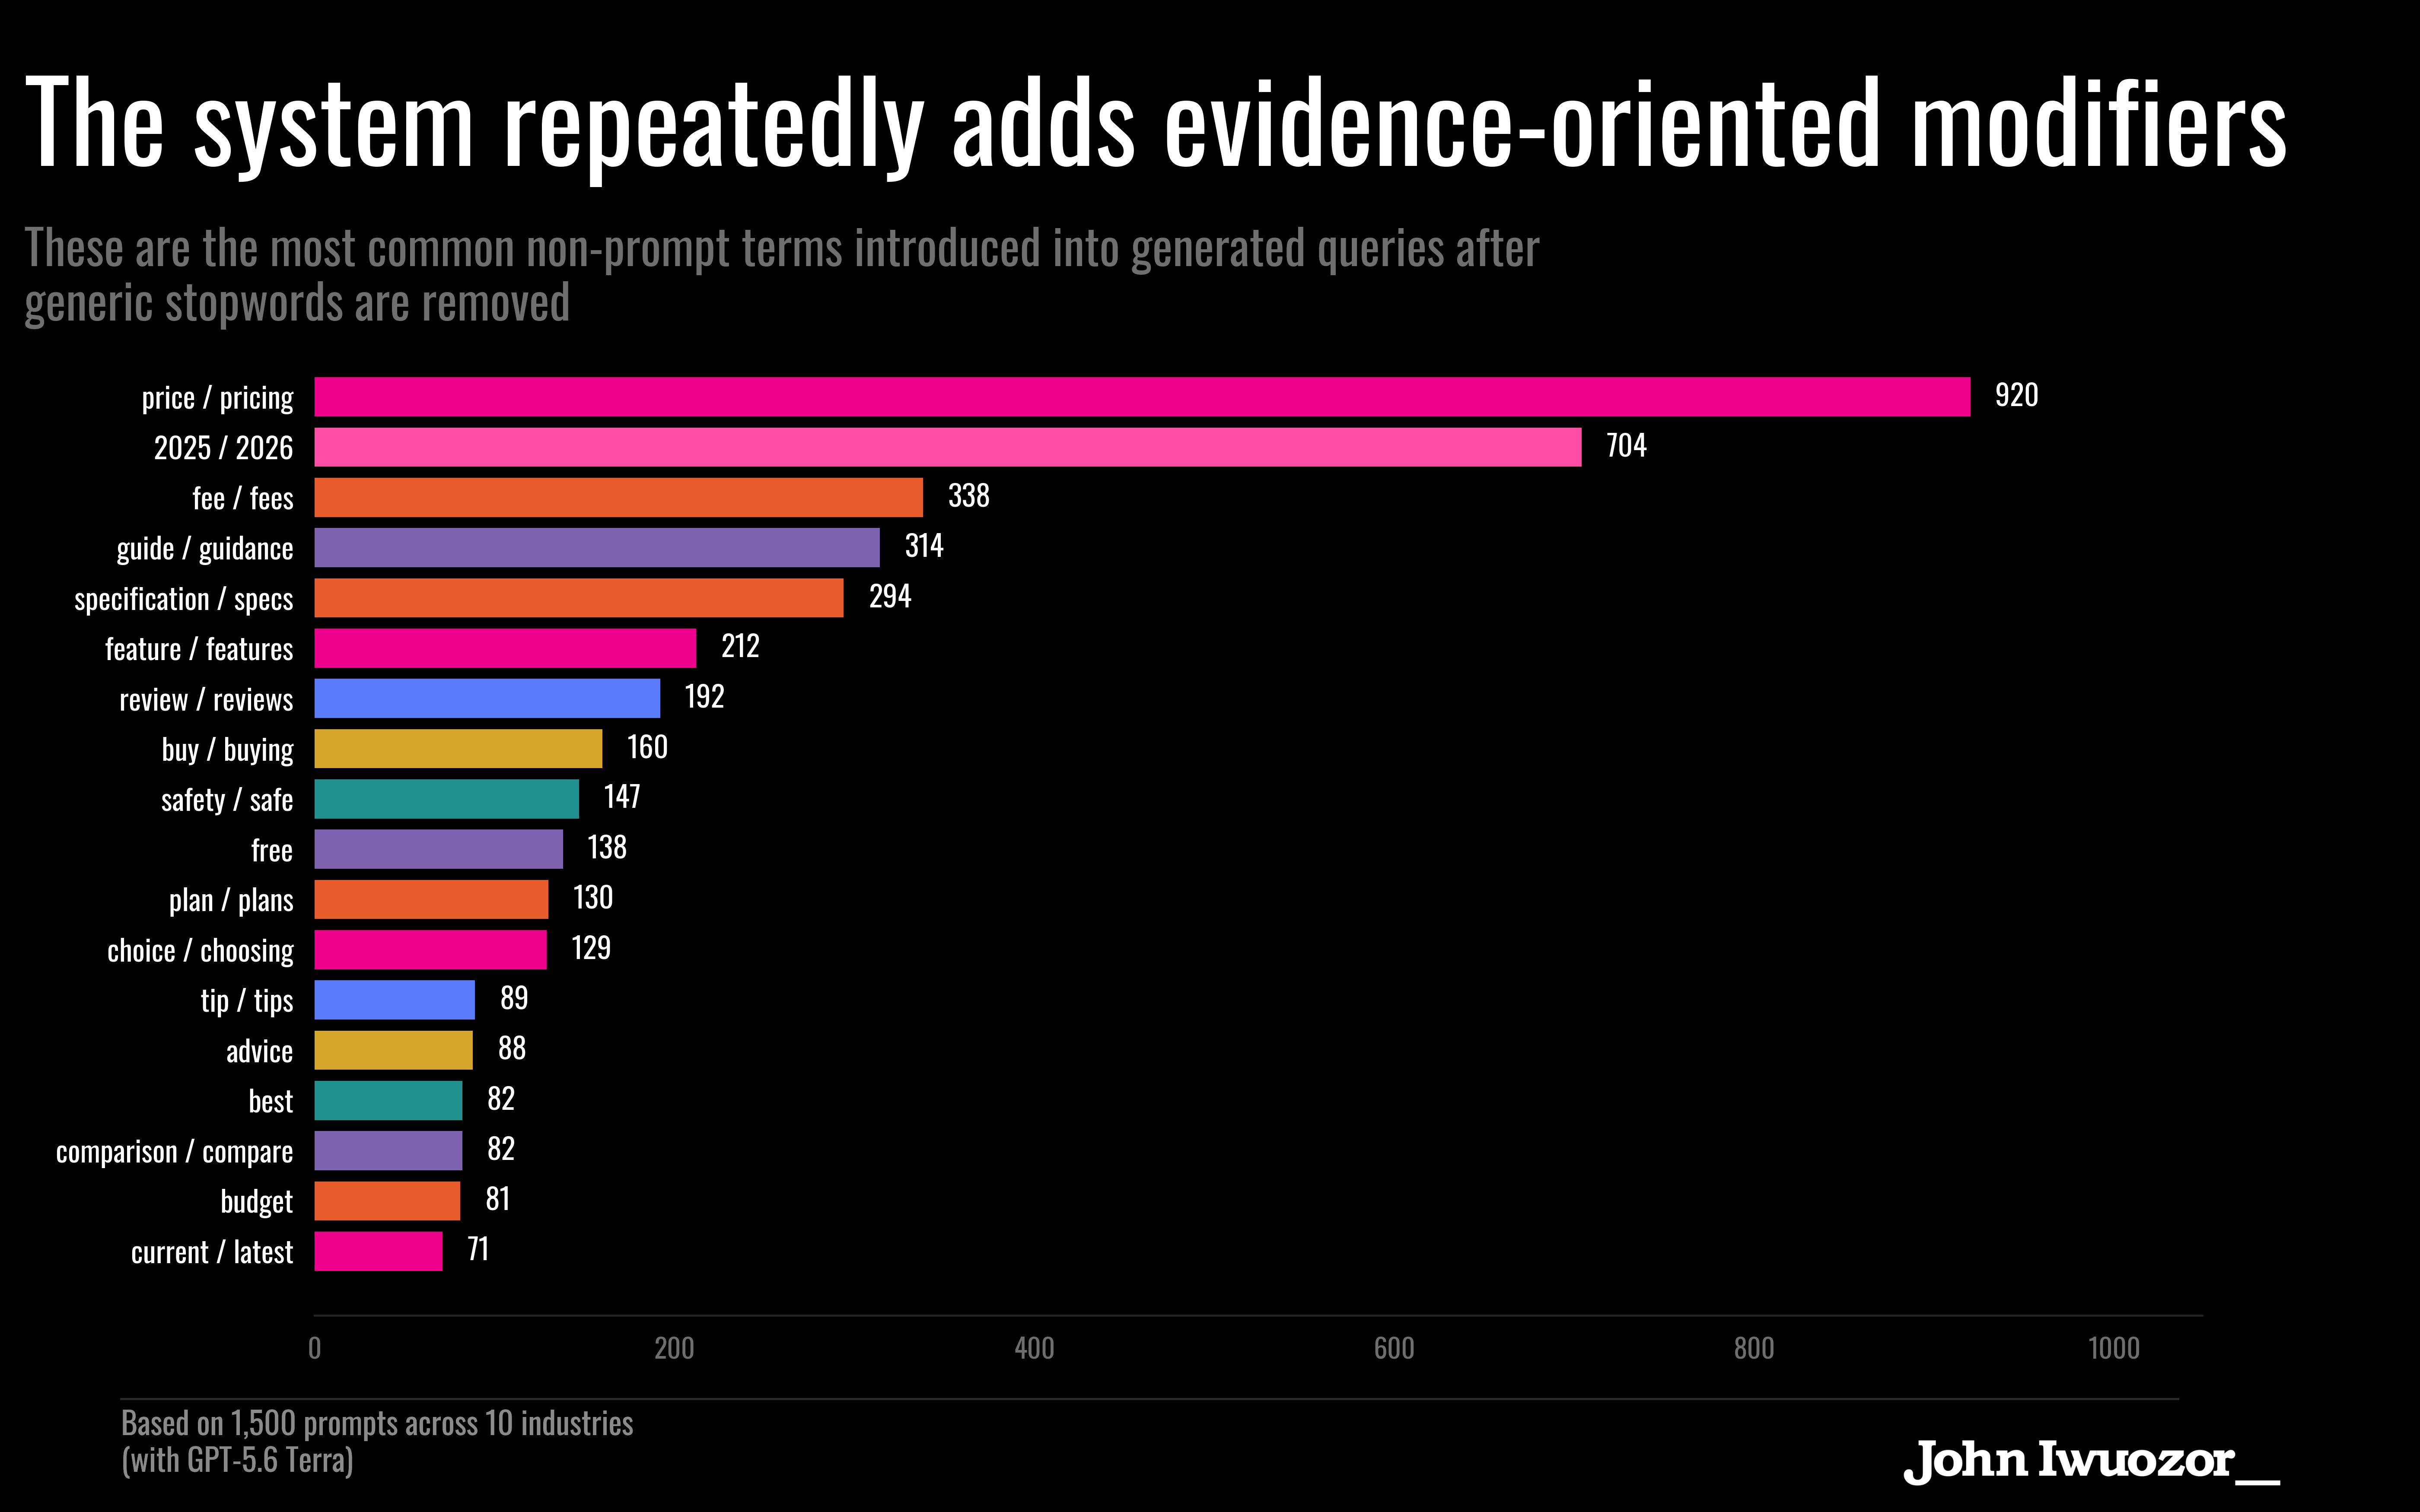
These are ordinary words, but together they show the model moving towards information that is current, specific and easier to confirm. That helps explain the heavy use of official websites.
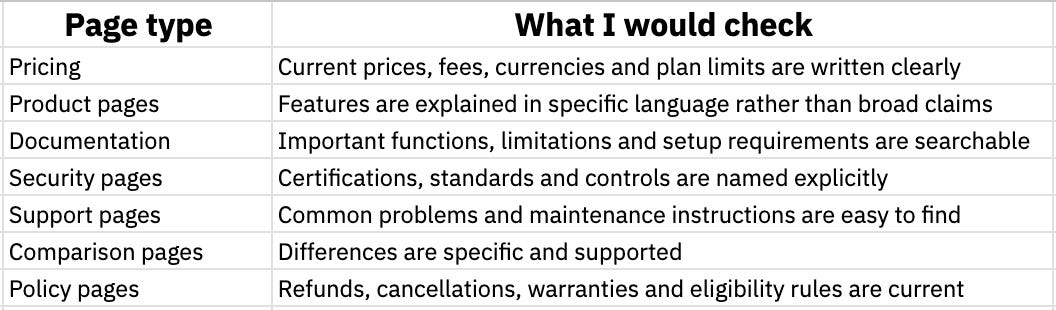
What I’m getting at is that a brand can publish excellent educational articles and still leave important retrieval gaps if its pricing pages, feature pages, policies and specifications are vague, outdated, hidden behind scripts or difficult to crawl.
Here’s a quick audit to carry out to know if you’re safe:
Comparison Prompts Almost Always Produced Tables
I also explored the editorial part of things and found that tables appeared in 23.3% of responses.
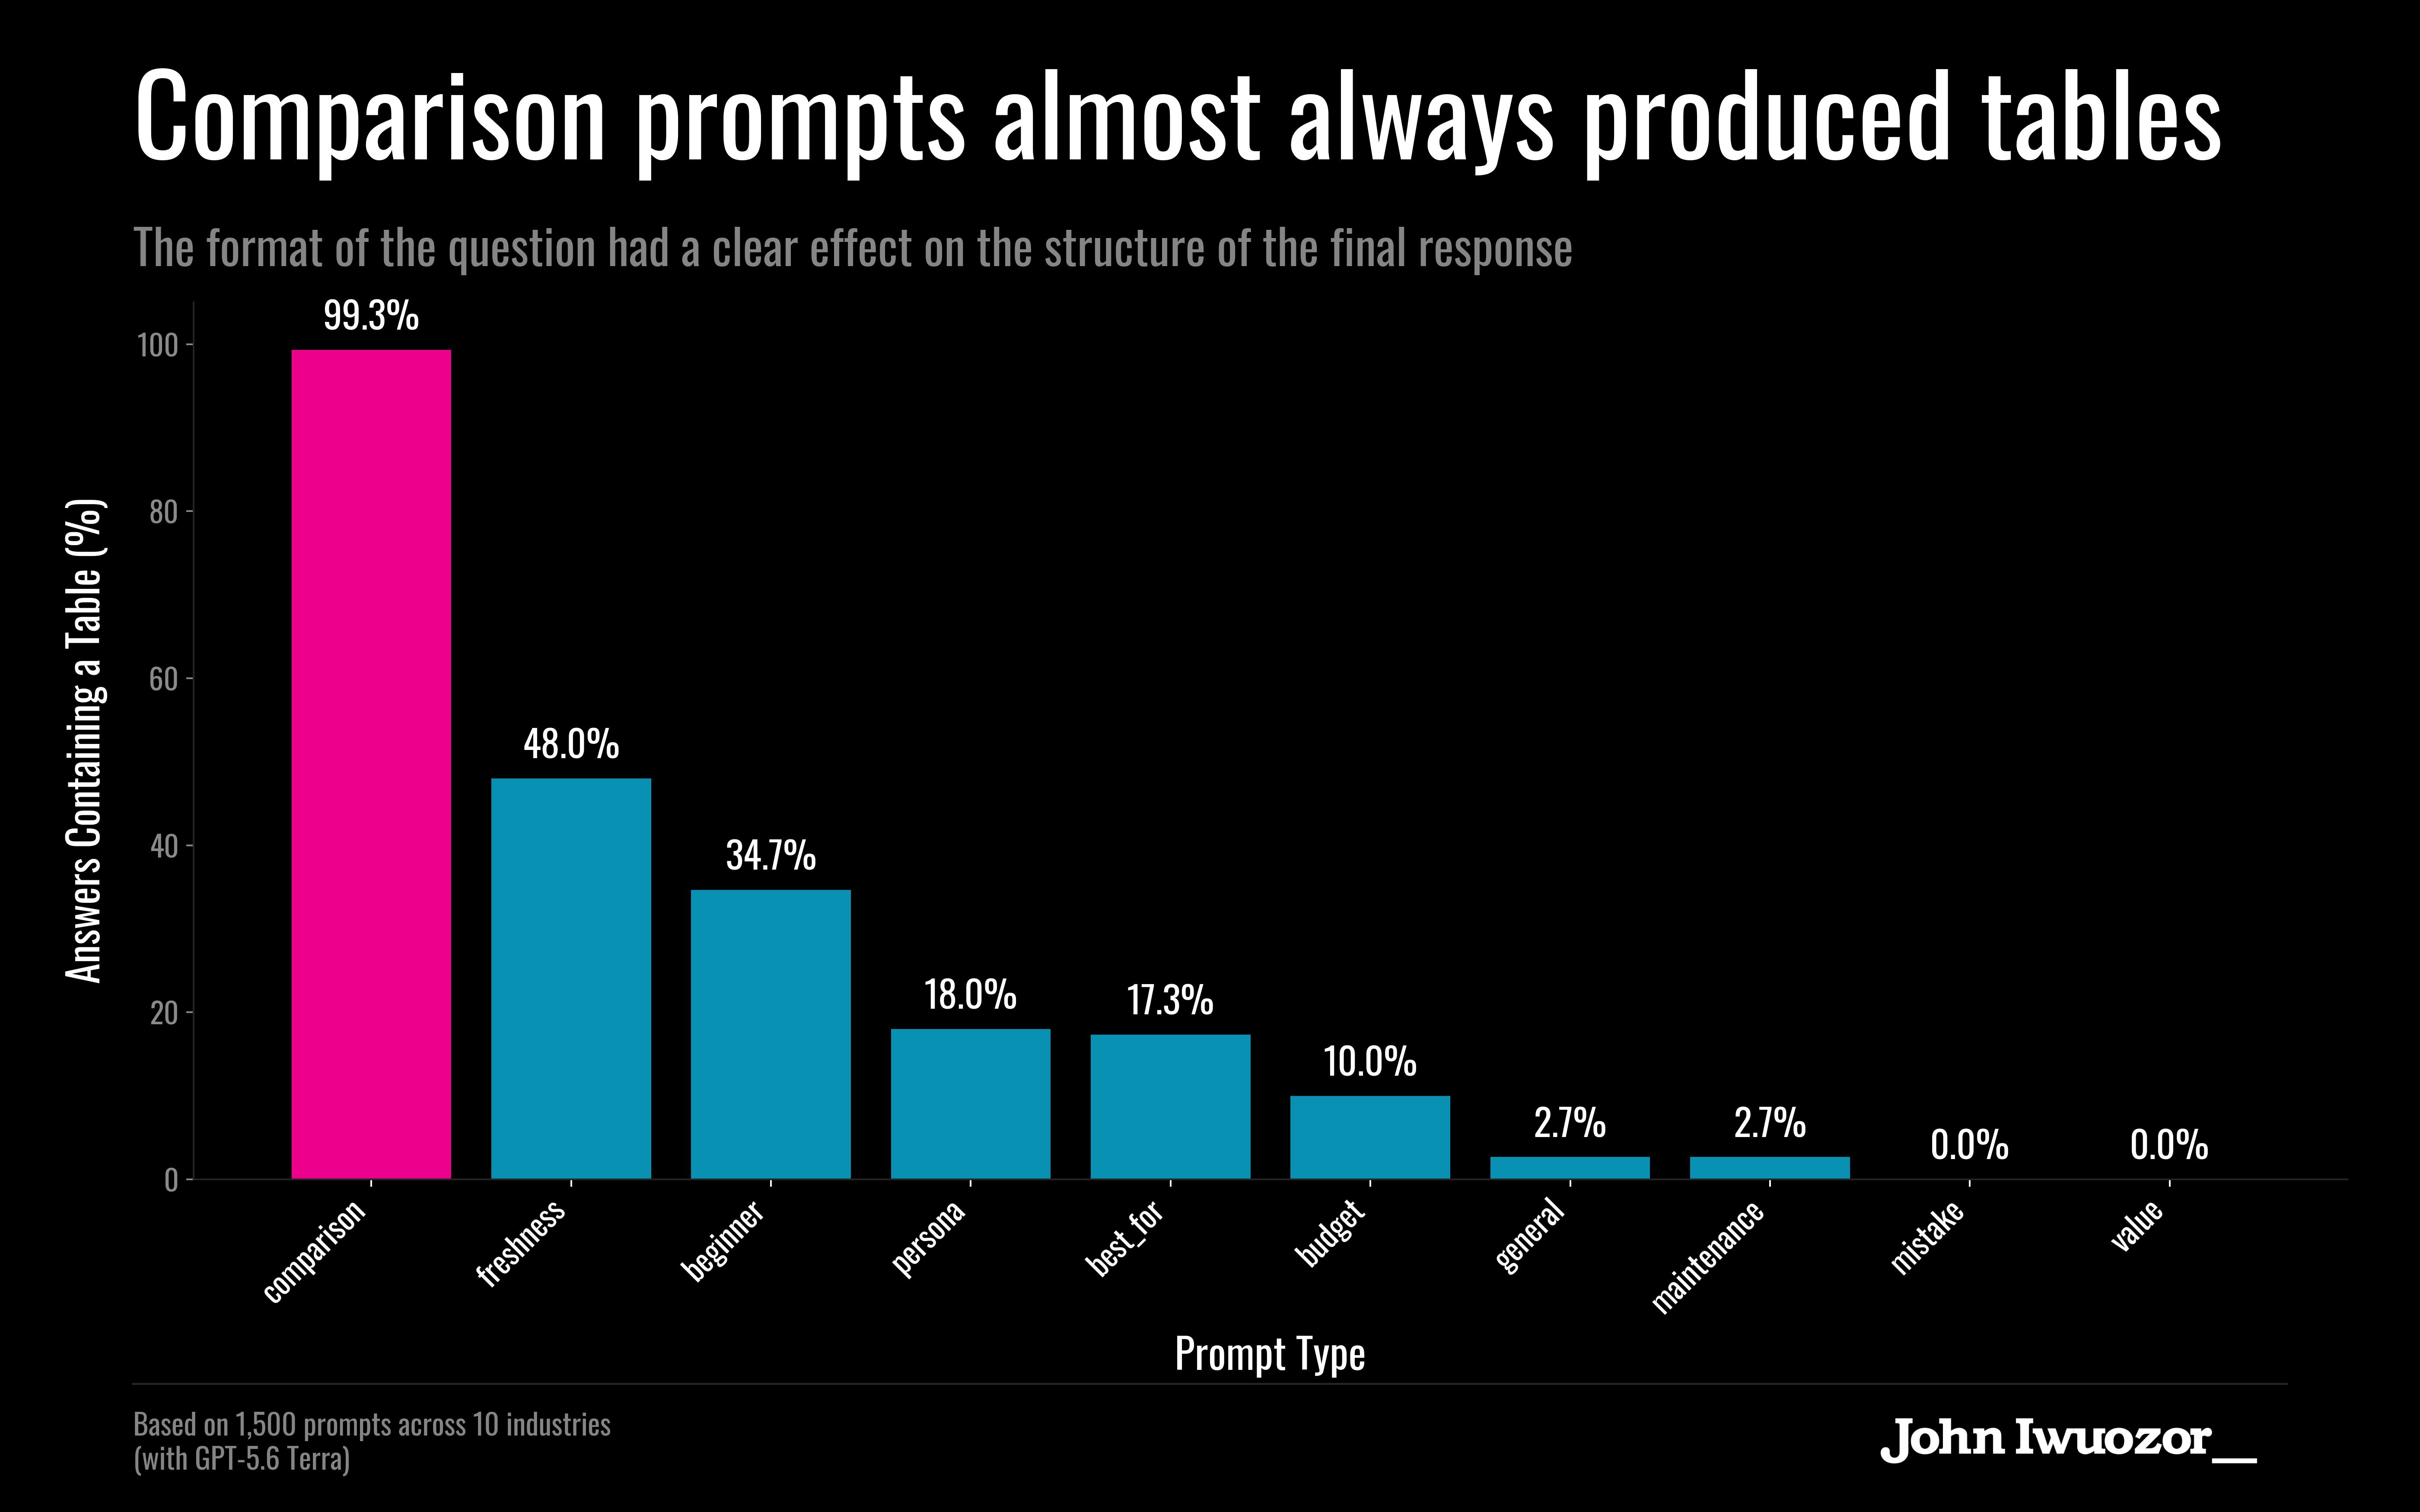
In that wide set, comparison prompts produced a table in 149 of 150 responses. That is a ridiculous level of consistency when you sit with it. That’s because comparison questions are treated as structured data problems almost every time, organising brands into rows and features, prices or use cases into columns.
This makes sense to imply that the questions asked are not only influencing what is being searched, but also how the final answer is organised, and, by extension, how brands were presented.
The takeaway here is not to start publishing random tables everywhere. It is to make comparison-ready information explicit and consistent: named plans, clear feature differences, supported claims and stable terminology.
Brand and Retail Sources Dominated the Citation Mix
After classifying the cited domains, brand and retailer domains formed the largest group by a wide margin. They accounted for 1,637 of 2,759 classified source appearances, or 59.3%.
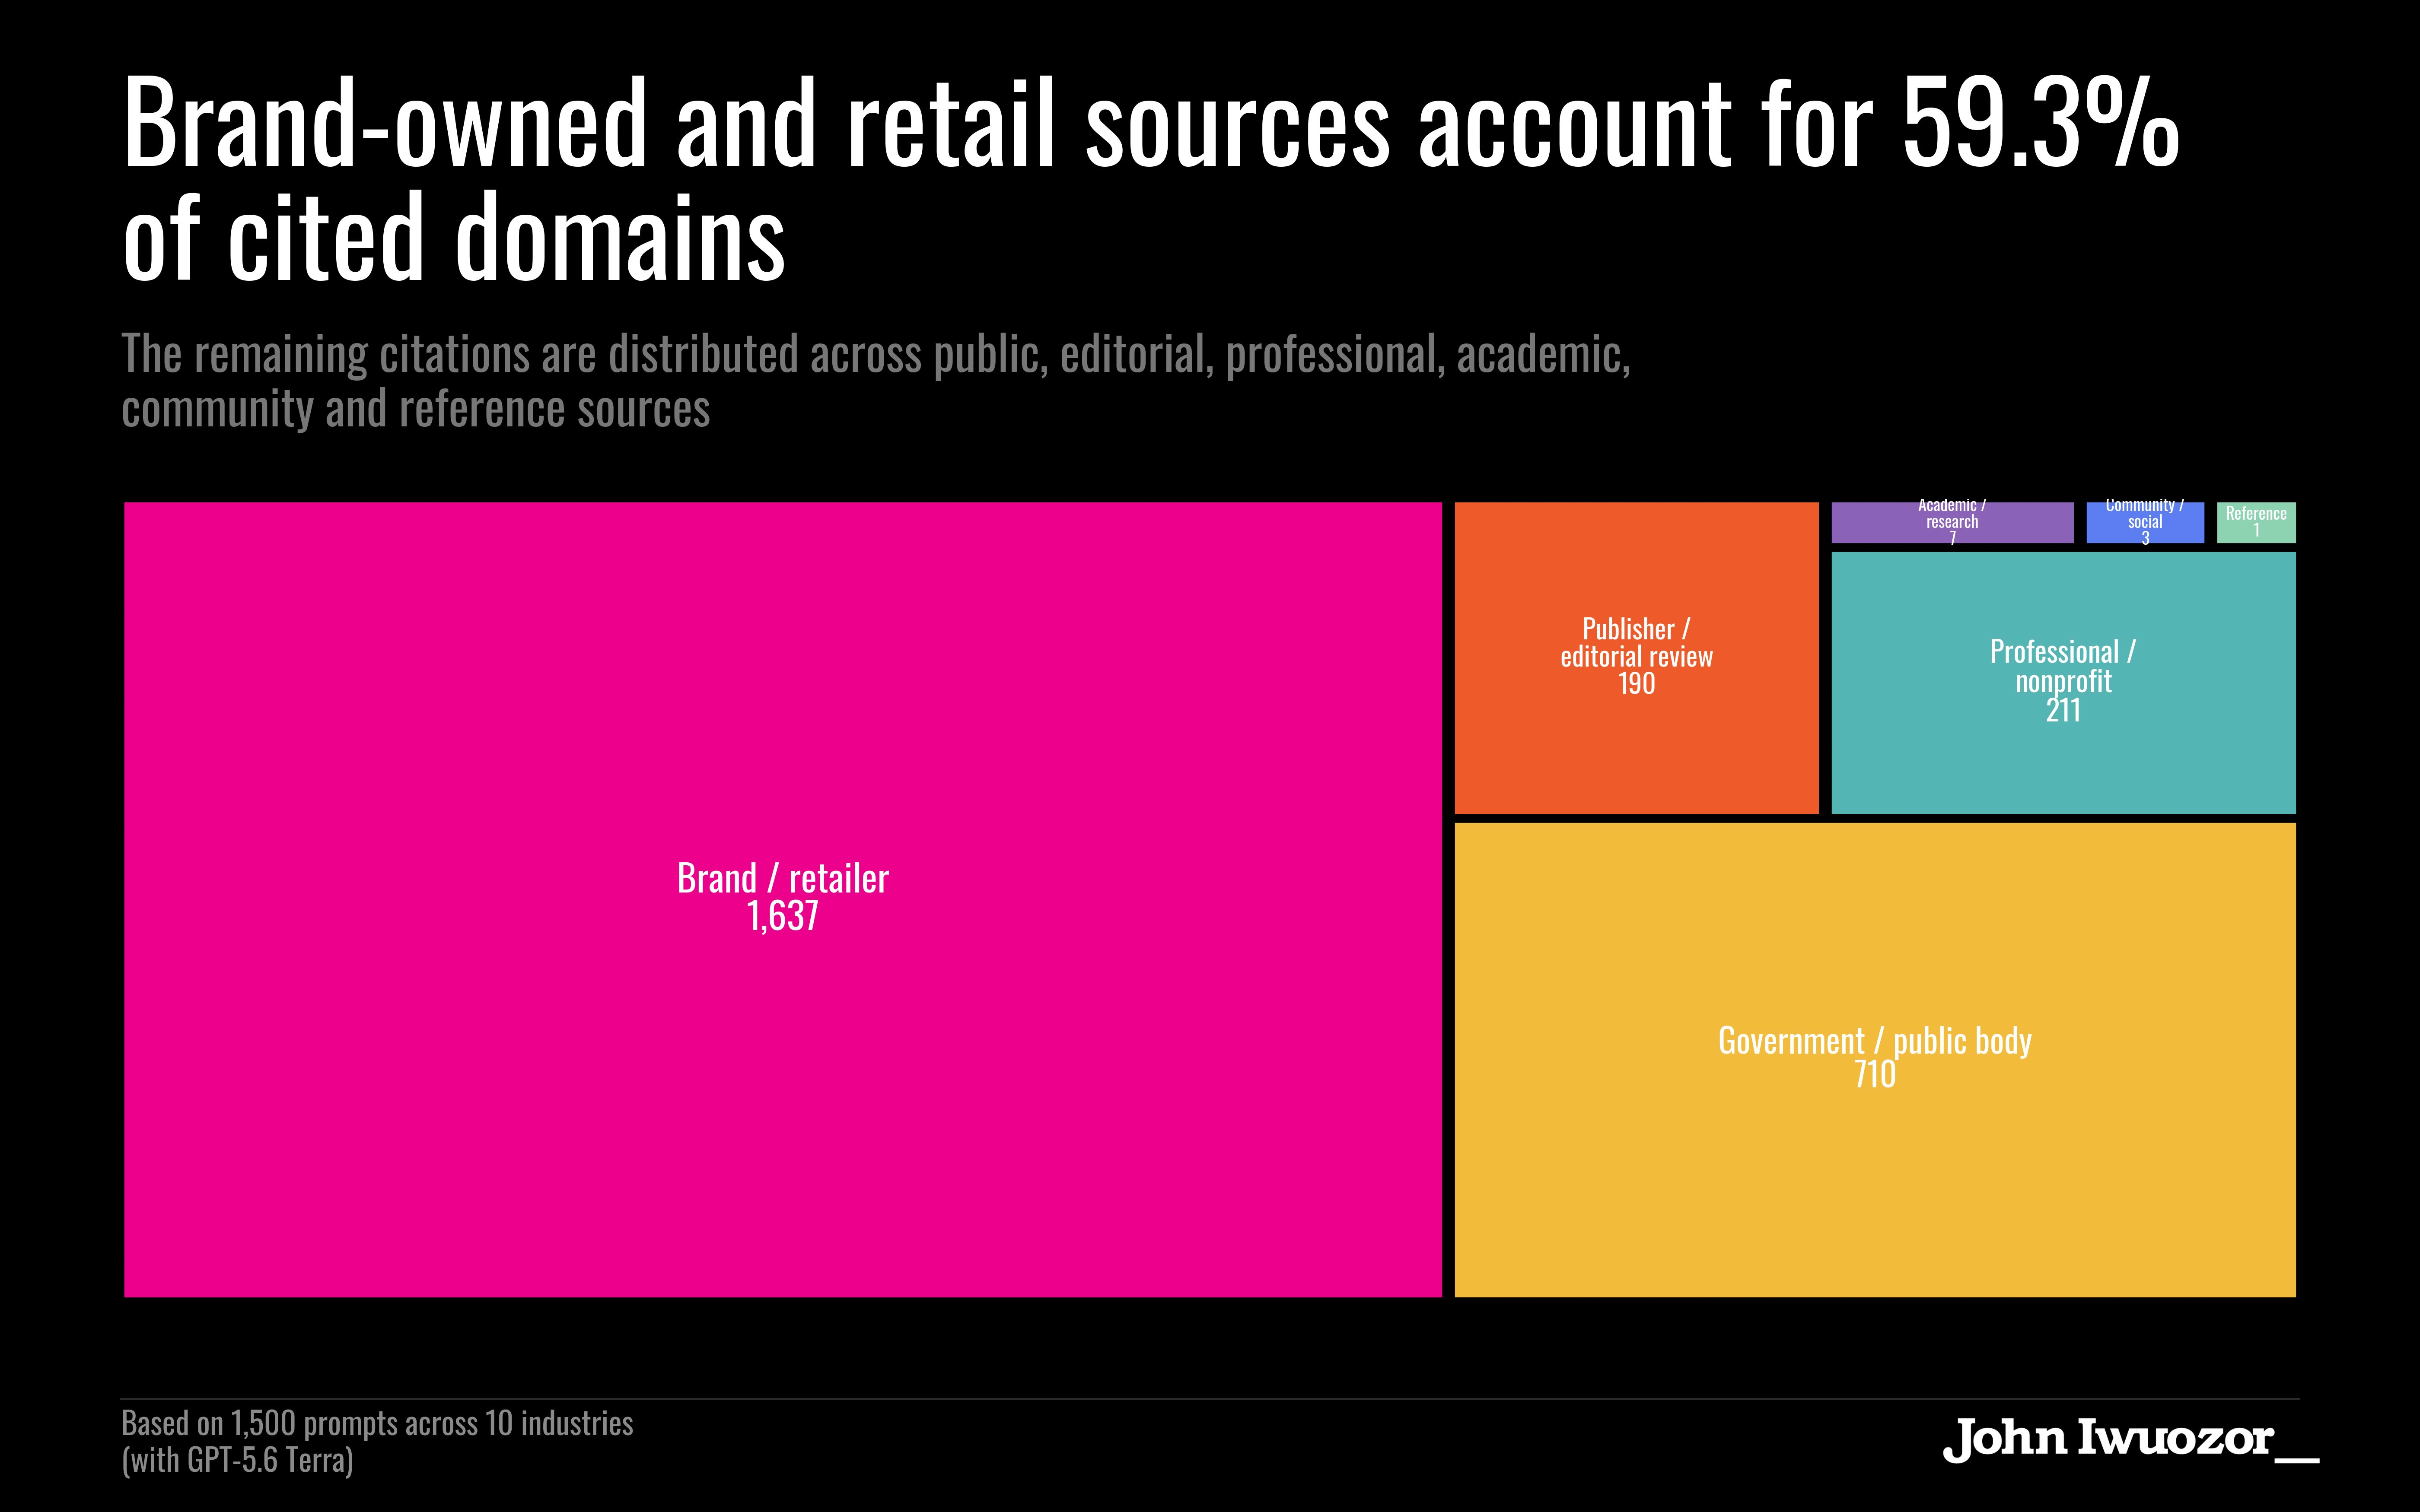
Government and public-body sources followed with 710 domain-response appearances. Professional and nonprofit sources contributed 211, while publishers and editorial review sites contributed 190. Academic, community and general reference sources were much smaller in this particular dataset.
This strengthens our earlier domain-selective finding. If ChatGPT repeatedly searches for pricing, official features, specifications and current product information, then first-party brand pages are naturally going to play a large role in the evidence it uses.
The Most-Cited Domains Were not Always the Most Widely Used
Drilling further, I realised that the 1,500 responses contained 4,533 citation appearances across 955 distinct domains.
The distribution had a long tail, but the top five domains accounted for 21.5% of all citation appearances, the top 10 accounted for 30.5%, and the top 50 accounted for 52.5%.
Citation volume and cross-industry reach told two different stories. AAD.org led the entire dataset with 315 citation appearances, but all of that reach came from one industry: health. Consumer.ftc.gov on the other hand, ranked third by volume at 206 appearances, yet travelled across nine industries and 40 subcategories.
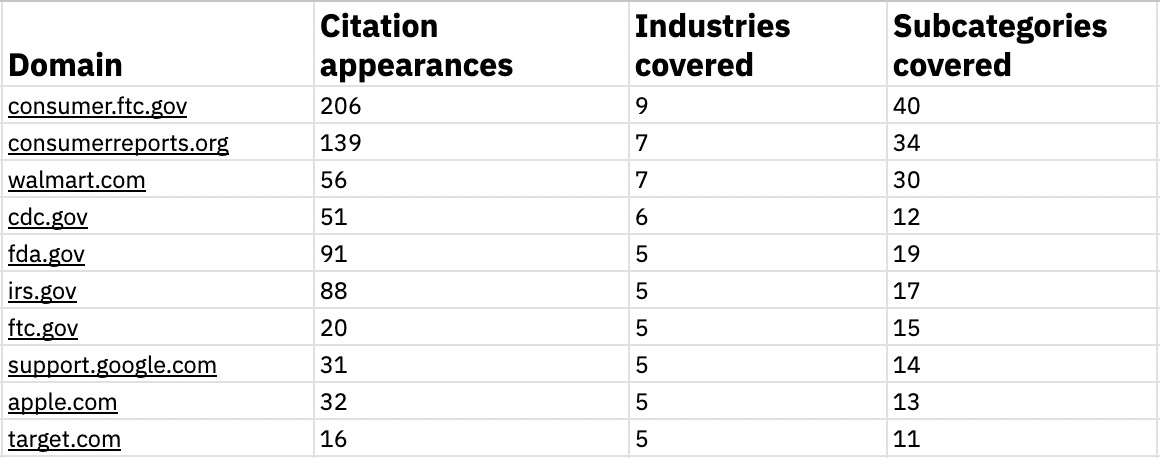
Looking at this table, the chosen domains are quite telling.
Starting with the FTC’s consumer site: Its pages cover scams, online shopping, consumer rights, fees, buying guidance and safety information to protect consumers against unfair or deceptive acts.
Consumer Reports plays a similar cross-category role through independent product testing and buying guidance. The CDC (health), FDA (food), IRS (finance), and FTC (trade) are narrower, but repeatedly useful whenever the model needs health, safety, food, tax or eligibility information.
These repeated appearances can be explained by a combination of broad coverage, clear public-interest information, strong search visibility, and stable pages.
This also shows the difference between being topical and being useful to the answer. A website does not need to cover every industry to become important.
What to Change/Fix in your SEO/GEO strategy After Seeing This
Win a place in ChatGPT’s “mind”. In 65.1% of first generated queries, ChatGPT was already using the ‘site:’ operator and telling the search engine which website to inspect. That means it’s already running with specific domains in mind even before retrieval begins. Possible ways to influence this include stronger brand recognition, third-party mentions, existing search visibility and clear associations with the category.
Treat official product pages as search content. A broad recommendation query can quickly become a direct check against pricing pages, specifications, integrations, cancellation terms or security documentation. Those pages need the same clarity, freshness and crawlability you would normally reserve for the blog.
Make important facts easy to find and difficult to misunderstand. State the price instead of saying plans are affordable, name the integrations instead of saying the product connects with popular tools, and list the security standards instead of relying on “enterprise-grade” language. Important details should not be buried inside videos, images or interactive elements. Clear facts give ChatGPT less room to guess or rely on another source.
Stop treating every tracked prompt as equally valuable. Informational prompts may show how ChatGPT explains a topic, but they often reveal very little about whether it will recommend, compare or mention a brand. Put more weight on commercial and decision-stage prompts where the user is choosing between options, checking price, looking for alternatives or trying to avoid a bad purchase. Those are the prompts where citation patterns, brand inclusion and direct website checks are more likely to translate into actual influence.
This is one of my first fully documented AEO/GEO research projects, and there will be more. If you found it useful, share it, send it to someone who will disagree with it, or reach out if you want to compare notes. I’m happy to share the dataset and methodology with people doing serious work in this space. Ciao ciao!
Solid first documented project! Some highlights I can also confirm...
Certain prompts lead to parametric knowledge even with web tools requested. Sometimes by simply changing to more thinking, the willingness to use a web tool increases. I am not sure if model updates change these a lot (I suspect not), so I look forward to a longitudinal look on your methodology!
OpenAI release notes: https://help.openai.com/en/articles/6825453-chatgpt-release-notes
The query reformulation/fan-out modifiers do change after model updates and the use of site: operator is increasing in prominence. A lot of people assume our "PHD-level intelligence" writes out a college thesis of an answer by collecting sources first before writing out an answer, but the truth is that's not how most answers are given. A bias was already there from the training data and citations are just a form of sampling bias.